> ## Documentation Index
> Fetch the complete documentation index at: https://docs.vowen.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Models & Engines
> Choose the right speech-to-text model for your use case.
Vowen runs your dictation through a speech model of your choice. Some run entirely on your machine, some are cloud APIs you connect with your own key, and one lets you point Vowen at a server you run yourself.
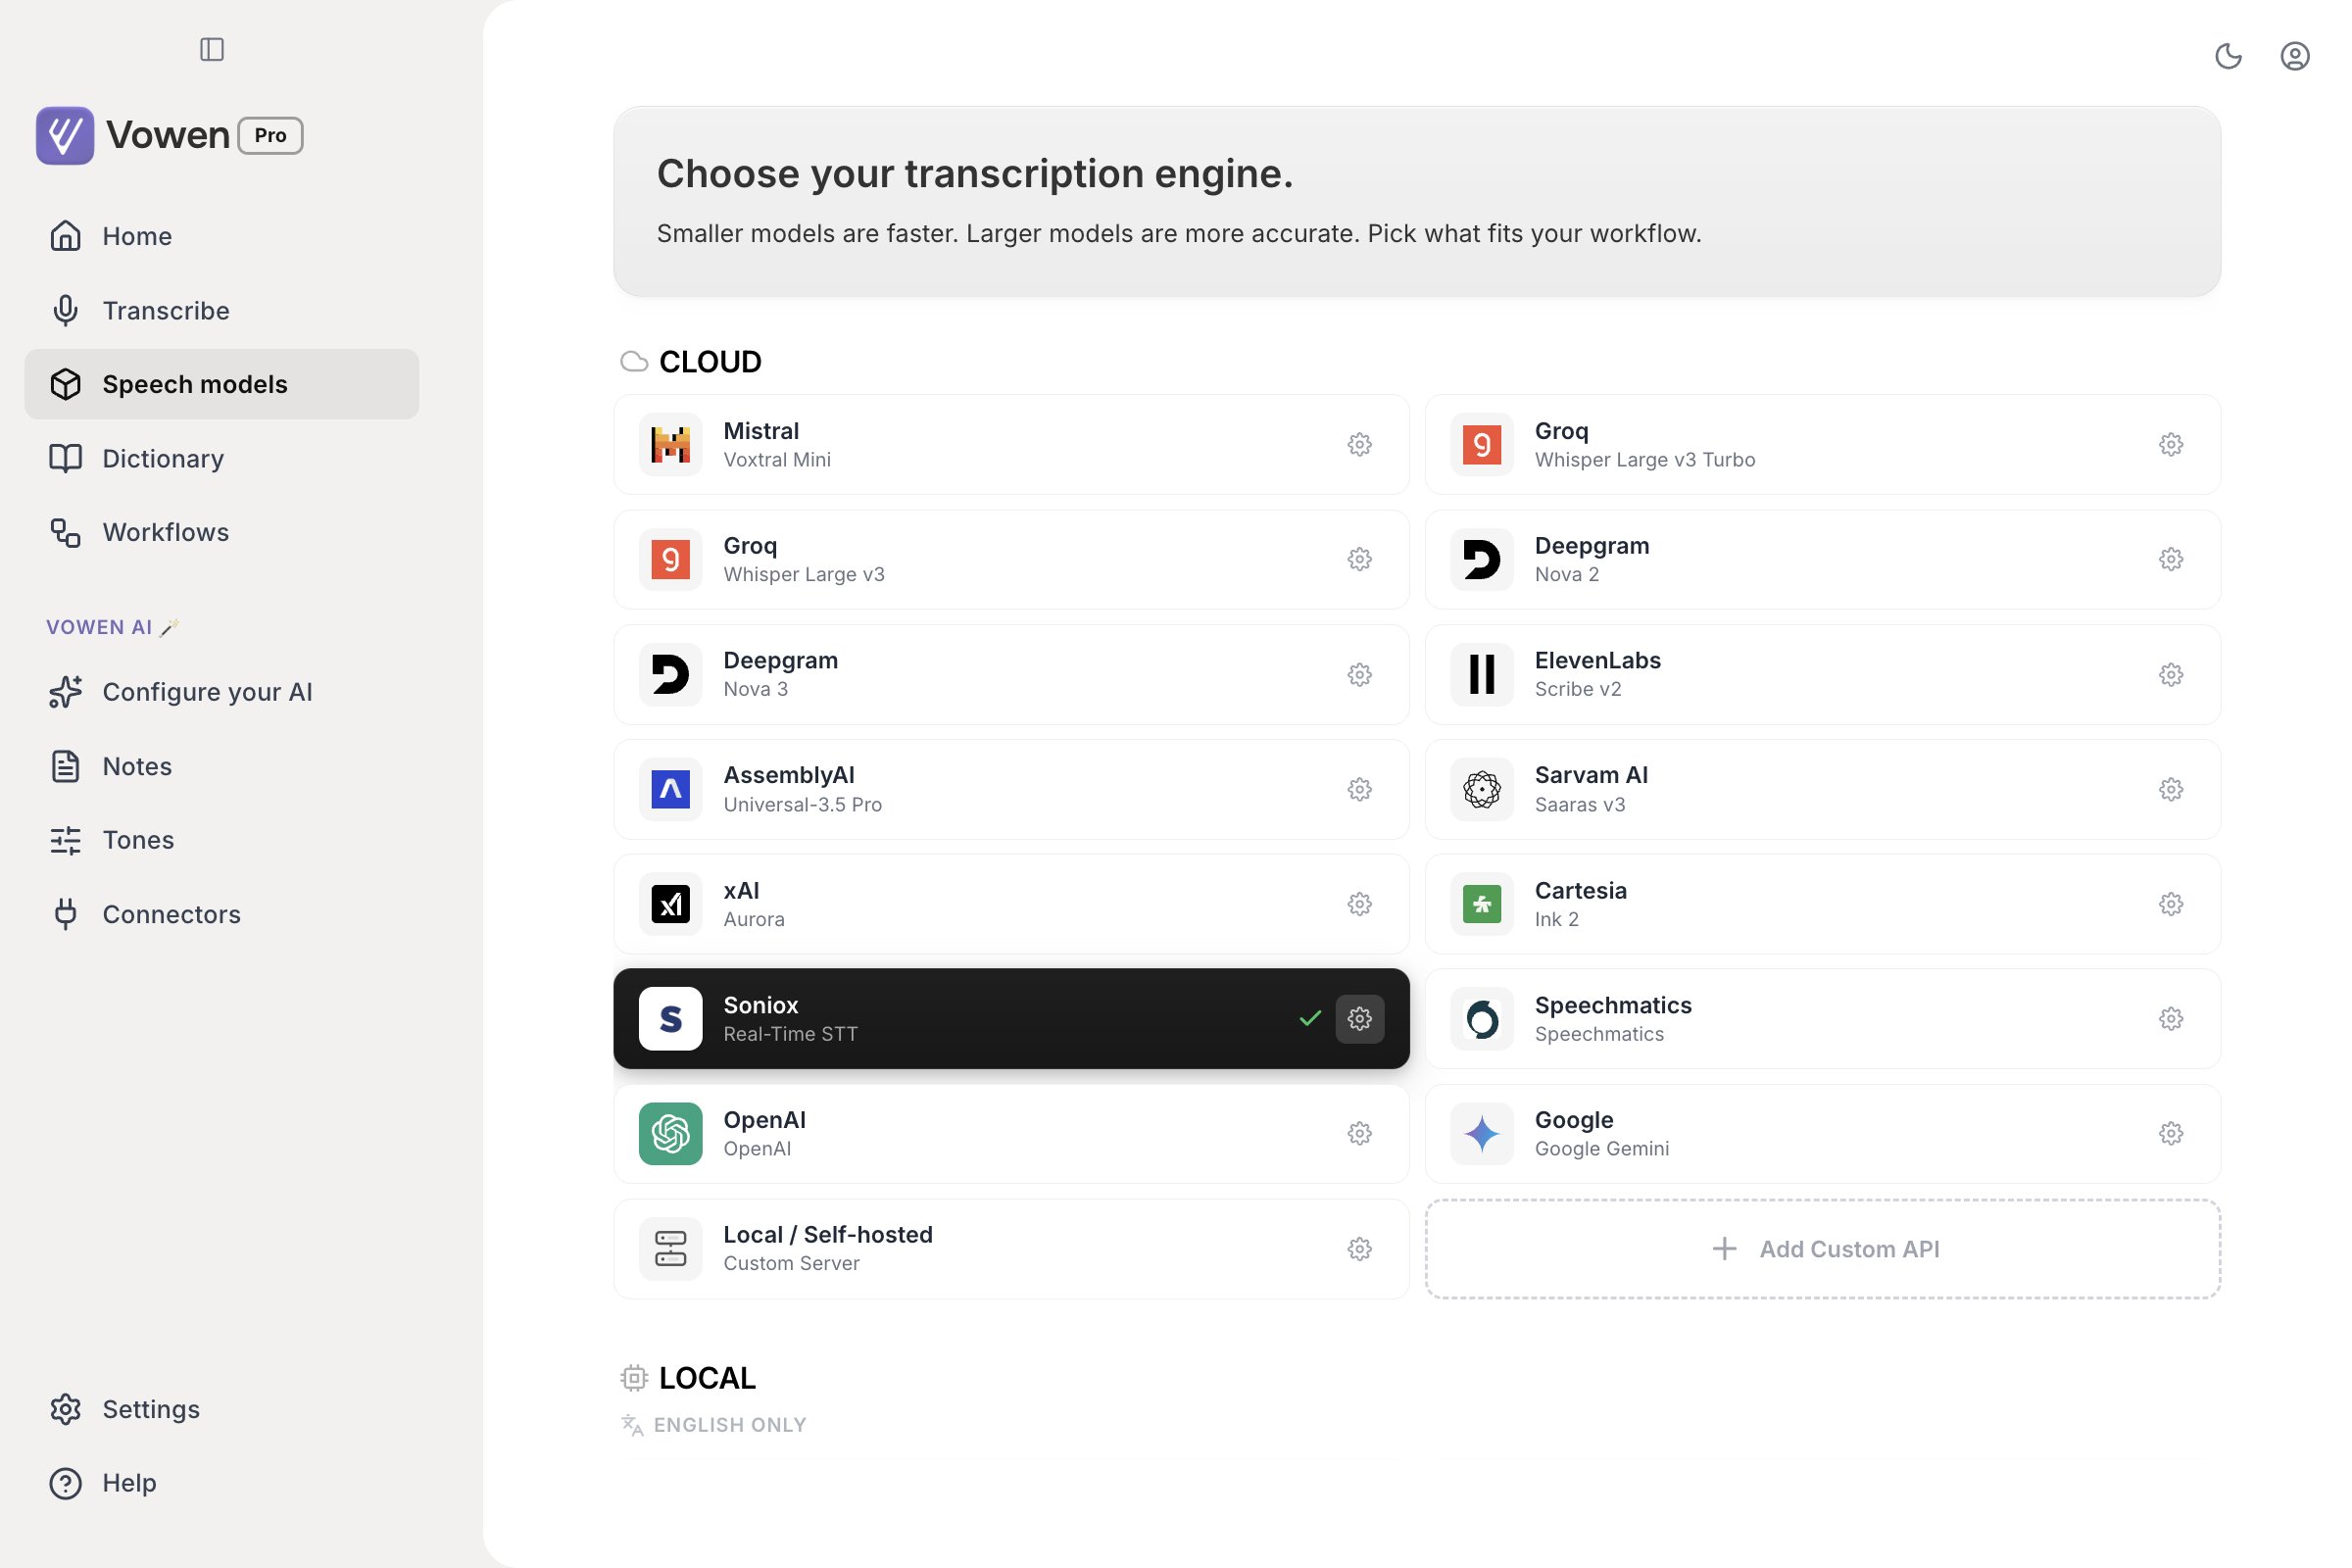
All of them live on the **Speech models** page in the left sidebar. That page has three sections: **Cloud**, **Local** (split into English Only and Multilingual), and, on Windows, **GPU Acceleration**.
 ## Quick recommendations
| Use case | Recommended model | Why |
| - | - | - |
| Everyday English (macOS, Windows) | Parakeet V2 | The default. Offline, fast, English-only |
| Everyday multilingual (macOS, Windows) | Parakeet V3 | Offline, auto-detects 25 European languages |
| Live preview with punctuation (macOS) | Nemotron EN or Nemotron Multilingual | The only local models whose partial results are already punctuated |
| Maximum offline accuracy | Whisper Large v3 Turbo | Best local accuracy per second of processing |
| Fastest cloud accuracy on a free tier | Whisper Large v3 Turbo (Groq) | Generous free tier, very fast |
| Non-English via cloud | Whisper Large v3 (Groq) or Nova 3 (Deepgram) | Strong multilingual coverage |
| Indian languages | Saaras v3 (Sarvam AI) | 22 Indian languages plus English |
| Japanese | Parakeet Japanese (macOS) or a cloud model | Purpose-trained local option |
| Mandarin | Parakeet Mandarin (macOS) or a cloud model | Purpose-trained local option |
| Meetings where you need speaker labels | Nova 3, Scribe v2, Universal-3.5 Pro, or local Parakeet / Whisper | See [Speaker identification](#speaker-identification) |
| Maximum privacy | Any local model | Audio never leaves your device |
## Local models
Local models run entirely on your machine and need no internet connection. Nothing is bundled with the installer. You download every local model on demand from the Speech models page. See [Model Download & Management](/transcription/model-download).
Sizes below are the download sizes as the app reports them.
### Parakeet
NVIDIA's Parakeet family. Vowen ships four separate Parakeet models, not one. Each is a different set of weights with its own language coverage and its own capabilities.
| Model | Platforms | Download | Languages | Live streaming | Timestamps | Speaker labels |
| - | - | - | - | - | - | - |
| **Parakeet V2** (default) | macOS, Windows | 430 MB (macOS) / 451 MB (Windows) | English only | Yes (macOS) | Yes | Yes |
| **Parakeet V3** | macOS, Windows | 445 MB (macOS) / 478 MB (Windows) | 25 European languages, auto-detected | Yes (macOS) | Yes | Yes |
| **Parakeet Japanese** | macOS | 532 MB | Japanese only | No | Yes | No |
| **Parakeet Mandarin** | macOS | 1.5 GB | Mandarin Chinese only | No | No | No |
**Parakeet Mandarin** returns plain text only: no per-word timings, so no clickable timestamps and no subtitle export, no live preview, and no speaker labels. Everything else about it works normally.
**Parakeet Japanese and Mandarin are macOS only.** There is no Windows build, and on Windows the Speech models page simply does not list them.
On macOS, Parakeet V2 and V3 also pull down a small **end-of-utterance streaming model** in the background. It is what powers the live transcription preview. You never pick it or see it in the model list. See [the download page](/transcription/model-download#the-hidden-streaming-model) for what it is and when it gets removed.
### Nemotron (macOS, Apple Silicon)
NVIDIA Nemotron Speech models. Both stream natively, and unlike Parakeet their live preview arrives already punctuated and capitalized. It reads as finished text while you are still speaking, instead of arriving as a lowercase run-on that gets fixed at the end.
| Model | Platforms | Download | Languages | Live streaming | Timestamps | Speaker labels |
| - | - | - | - | - | - | - |
| **Nemotron EN** | macOS (Apple Silicon) | 528 MB | English only | Yes, punctuated | No | No |
| **Nemotron Multilingual** | macOS (Apple Silicon) | 588 MB | 31 languages | Yes, punctuated | No | No |
Nemotron transcribes files with the same engine it uses for dictation, so its output carries no per-segment timings.
See [Languages](/transcription/languages#nemotron-multilingual) for the full 31-language list.
### Whisper
OpenAI's Whisper, running locally on your own machine. 99 languages on the multilingual variants.
| Model | Download | Speed | Accuracy | Best for |
| - | - | - | - | - |
| Tiny | 74 MB | Fastest | Basic | Quick notes, testing |
| Tiny (EN) | 74 MB | Fastest | Basic (English) | Fast English dictation |
| Base | 141 MB | Fast | Good | Multilingual basics |
| Base (EN) | 141 MB | Fast | Good | General English use |
| Small | 465 MB | Medium | Great | Professional work |
| Small (EN) | 465 MB | Medium | Great (English) | Detailed English |
| Medium | 1.4 GB | Slow | Excellent | High-quality output |
| Medium (EN) | 1.4 GB | Slow | Excellent (English) | Long-form English |
| Large v3 | 2.9 GB | Slowest | Best | Maximum accuracy |
| Large v3 Turbo | 1.5 GB | Medium-Fast | Excellent | Best balance |
The **(EN)** models are English-only and slightly more accurate for English than their multilingual counterparts of the same size.
**Tiny and Base ignore your Dictionary.** Among the local Whisper sizes, only Small, Medium, Large v3 and Large v3 Turbo use your vocabulary. If you rely on custom vocabulary, use Small or larger. See [Accuracy](/transcription/accuracy#how-vocabulary-actually-reaches-each-model).
### Start-up cost
Ordinary dictations pay no model load cost. On macOS and Windows alike, a local model is loaded once and stays ready between dictations.
You do pay a one-time wait the first time a given model runs on your Mac, while it is optimized for your specific chip. That takes roughly 20 seconds, and noticeably longer the very first time. During that window the indicator shows "Optimizing Parakeet model", and a dictation you start anyway is saved for retry rather than transcribed. See [the download page](/transcription/model-download#first-run-optimization) for what to expect.
## Cloud models
Cloud models send audio to a third-party API. They need an internet connection and an API key that you supply. Vowen never charges you for cloud transcription; you pay the provider directly, and most have a free tier.
Counts below are the languages Vowen offers in the dictation language picker for that model. See [Languages](/transcription/languages#the-language-list-changes-with-your-model) for the lists themselves.
| Model | Provider | Dictation languages | Real-time streaming |
| - | - | - | - |
| Whisper Large v3 Turbo | Groq | 99 | No |
| Whisper Large v3 | Groq | 99 | No |
| Nova 2 | Deepgram | 33 | Yes |
| Nova 3 | Deepgram | 50 | Yes |
| Scribe v2 | ElevenLabs | Multilingual | Yes |
| Universal-3.5 Pro | AssemblyAI | 6 streaming / multilingual batch | Yes |
| Voxtral Mini | Mistral | 13 | Yes |
| Saaras v3 | Sarvam AI | 23 (22 Indian + English) | Yes |
| Real-Time STT | Soniox | 60+ | Yes |
| Aurora | xAI | 25 | Yes |
| Ink 2 | Cartesia | English | Yes |
| Speechmatics | Speechmatics | 39 | Yes |
| OpenAI | OpenAI | Multilingual | Yes |
| Gemini (Live + Flash) | Google | Multilingual | Yes |
| Custom Server | Yours | Depends on your server | No |
There is no `gpt-4o-transcribe` in Vowen. Dictation uses either **`gpt-live-transcribe`** (streams while you speak) or **`gpt-transcribe`** (transcribes after you stop), depending on the toggle described in [Per-model options](#per-model-options). File transcription always uses `gpt-transcribe`, except when speaker identification is on, which switches to `gpt-4o-transcribe-diarize`. That is the only OpenAI model that emits speaker labels, and the only one that accepts no vocabulary hints at all.
Dictation streams over WebSocket in six languages: English, Spanish, French, German, Italian and Portuguese. File transcription uses Universal-3.5 Pro for the 18 languages it natively supports and falls back to Universal-2 for anything else.
Streaming uses Gemini Live, whose sessions are capped at 15 minutes each. File transcription uses Gemini Flash and handles audio up to about 9.5 hours. Custom vocabulary and speaker labels both work on Gemini file transcription, but more weakly than on providers built for them.
Listed in the app as **Real-Time STT (Soniox)**. One entry covers both a real-time streaming model for dictation and an async model for file transcription, across 60+ languages. It is the strongest option in Vowen for switching languages mid-sentence.
Streaming-first, tuned for the lowest word error rate and the fastest live preview. **English only.** File transcription runs Cartesia's batch model, which does not use your Dictionary.
Groq's API returns text only. When you turn on speaker identification with a Groq model, Vowen runs its own on-device speaker pipeline over the audio afterwards, on macOS and Windows. See [Diarization](/meeting-notes/diarization).
### Setting up a cloud model
Click **Speech models** in the left sidebar. Cloud models are the first section.
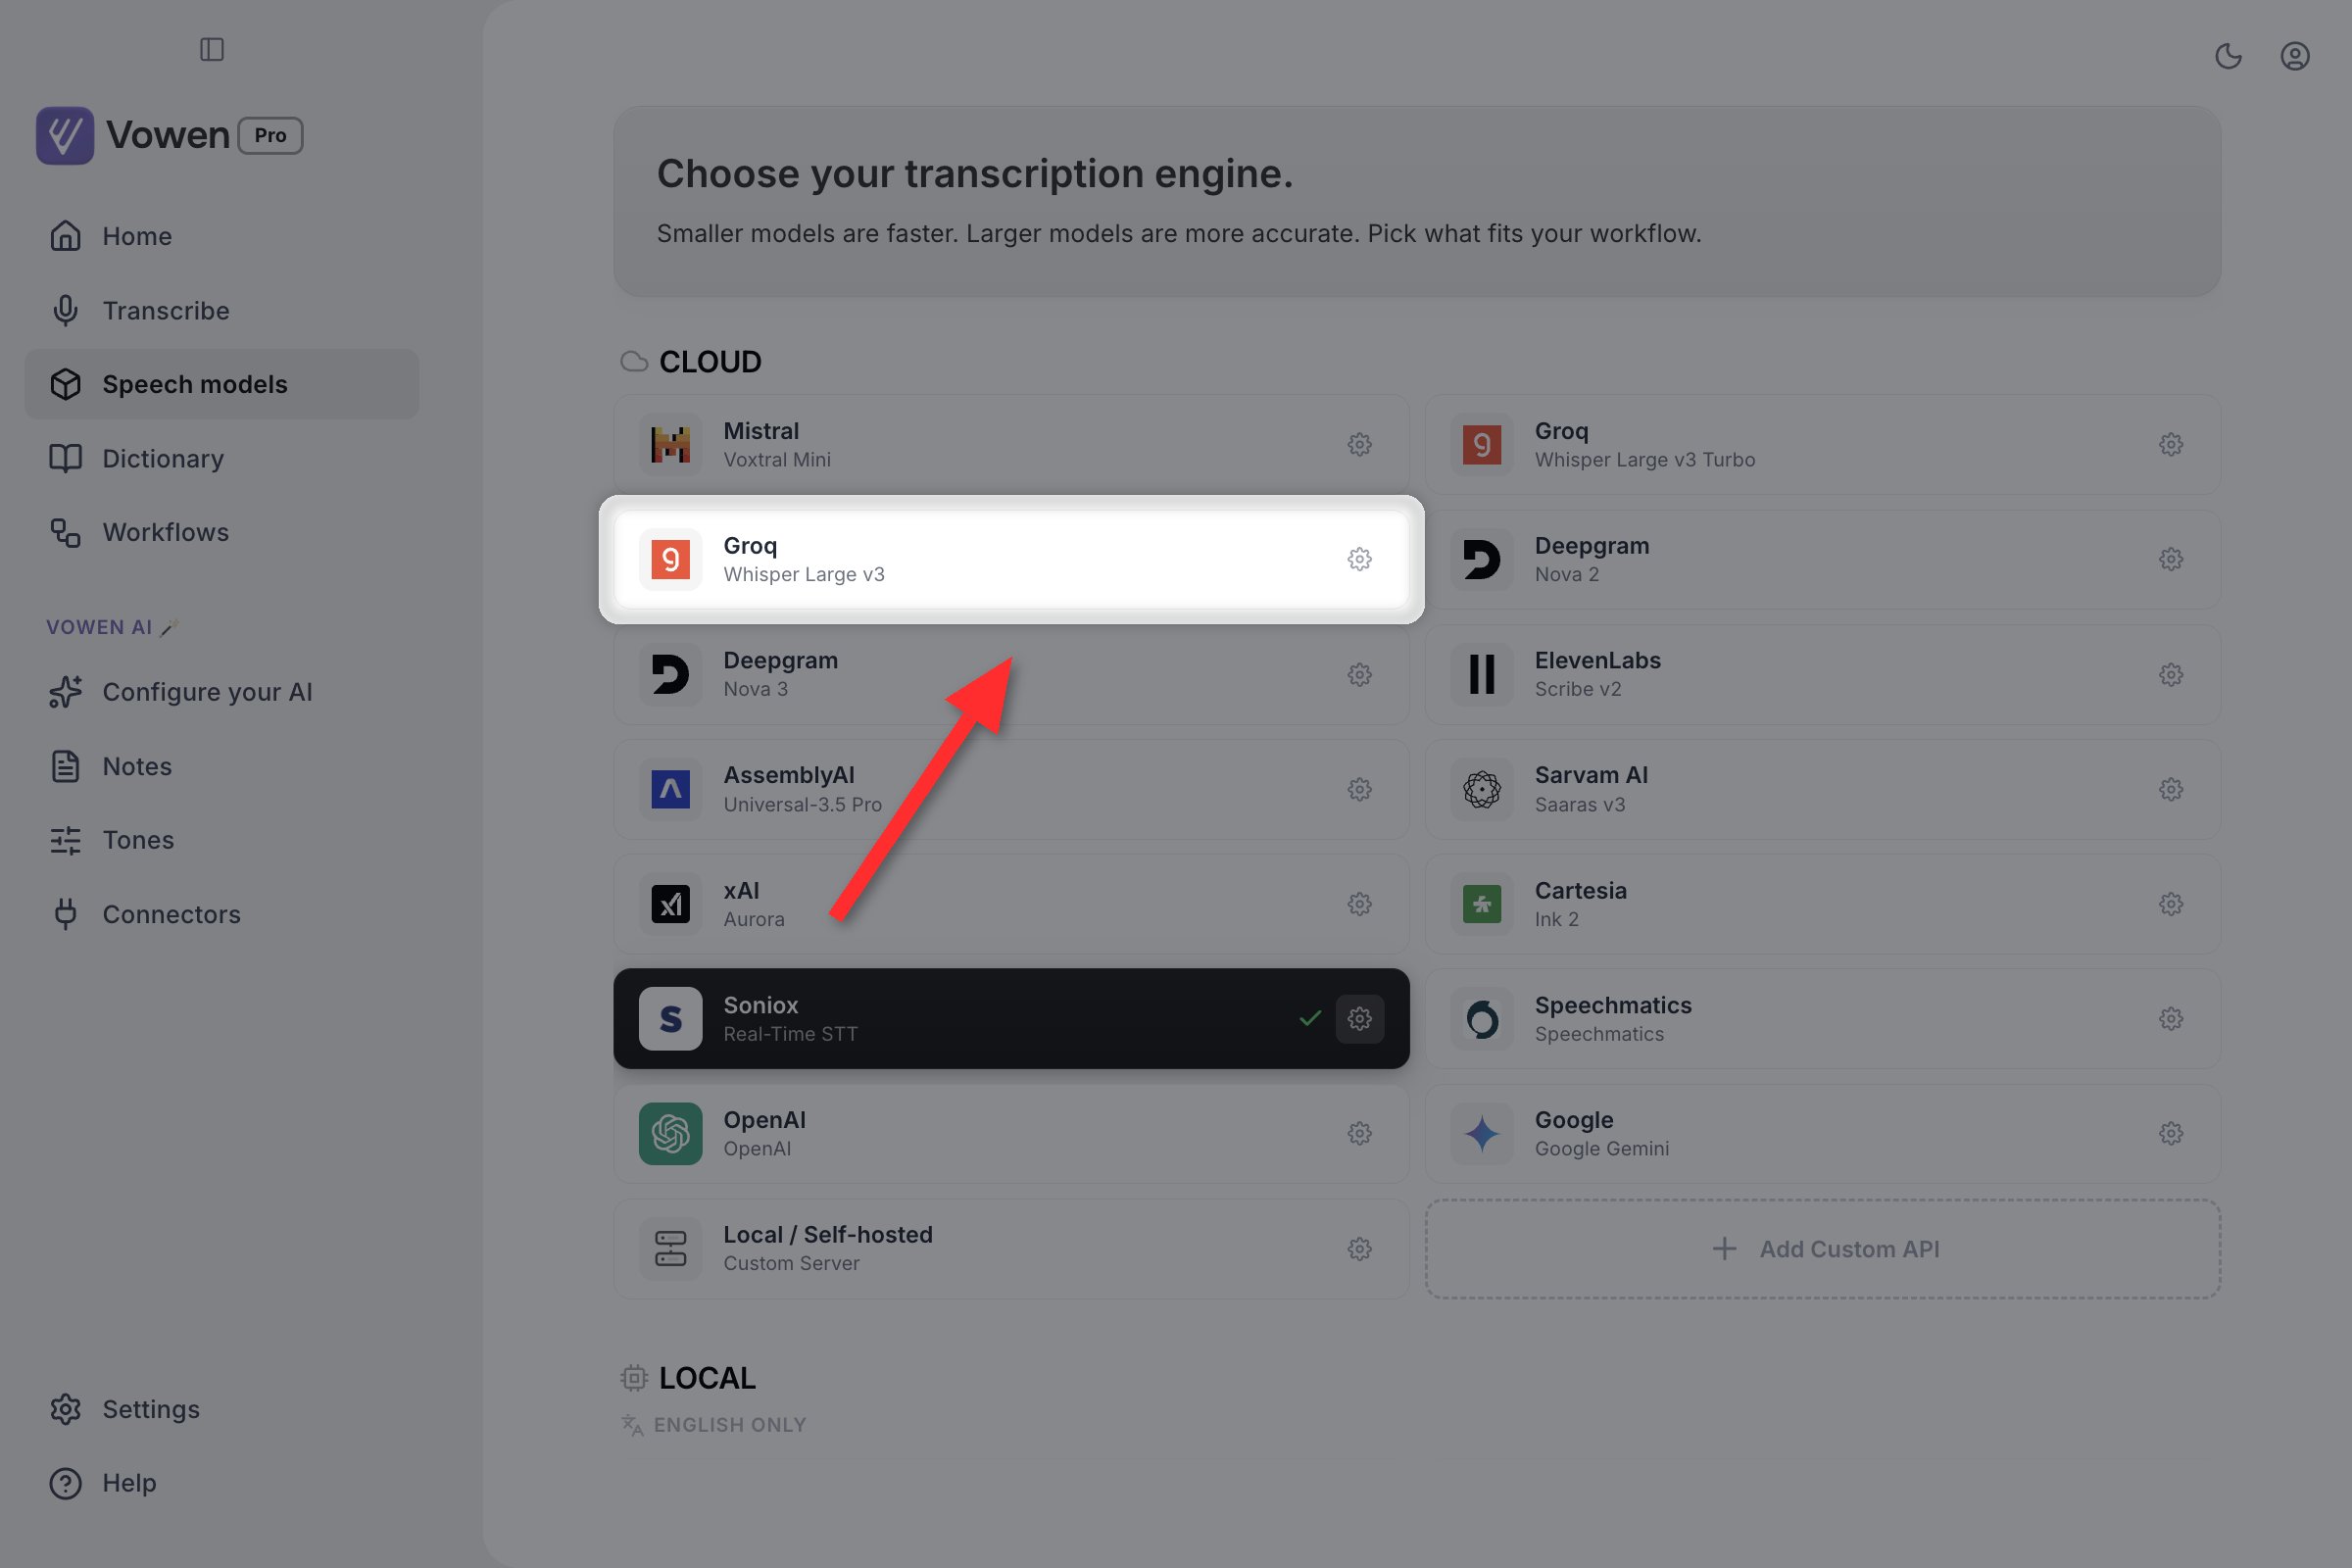
Click its card. A configuration panel opens showing the model's languages and capabilities.
This is true only for a provider you have not set up yet. Once a provider is configured, clicking its card **switches to that model** instead. Use the gear on the card to reopen its settings.
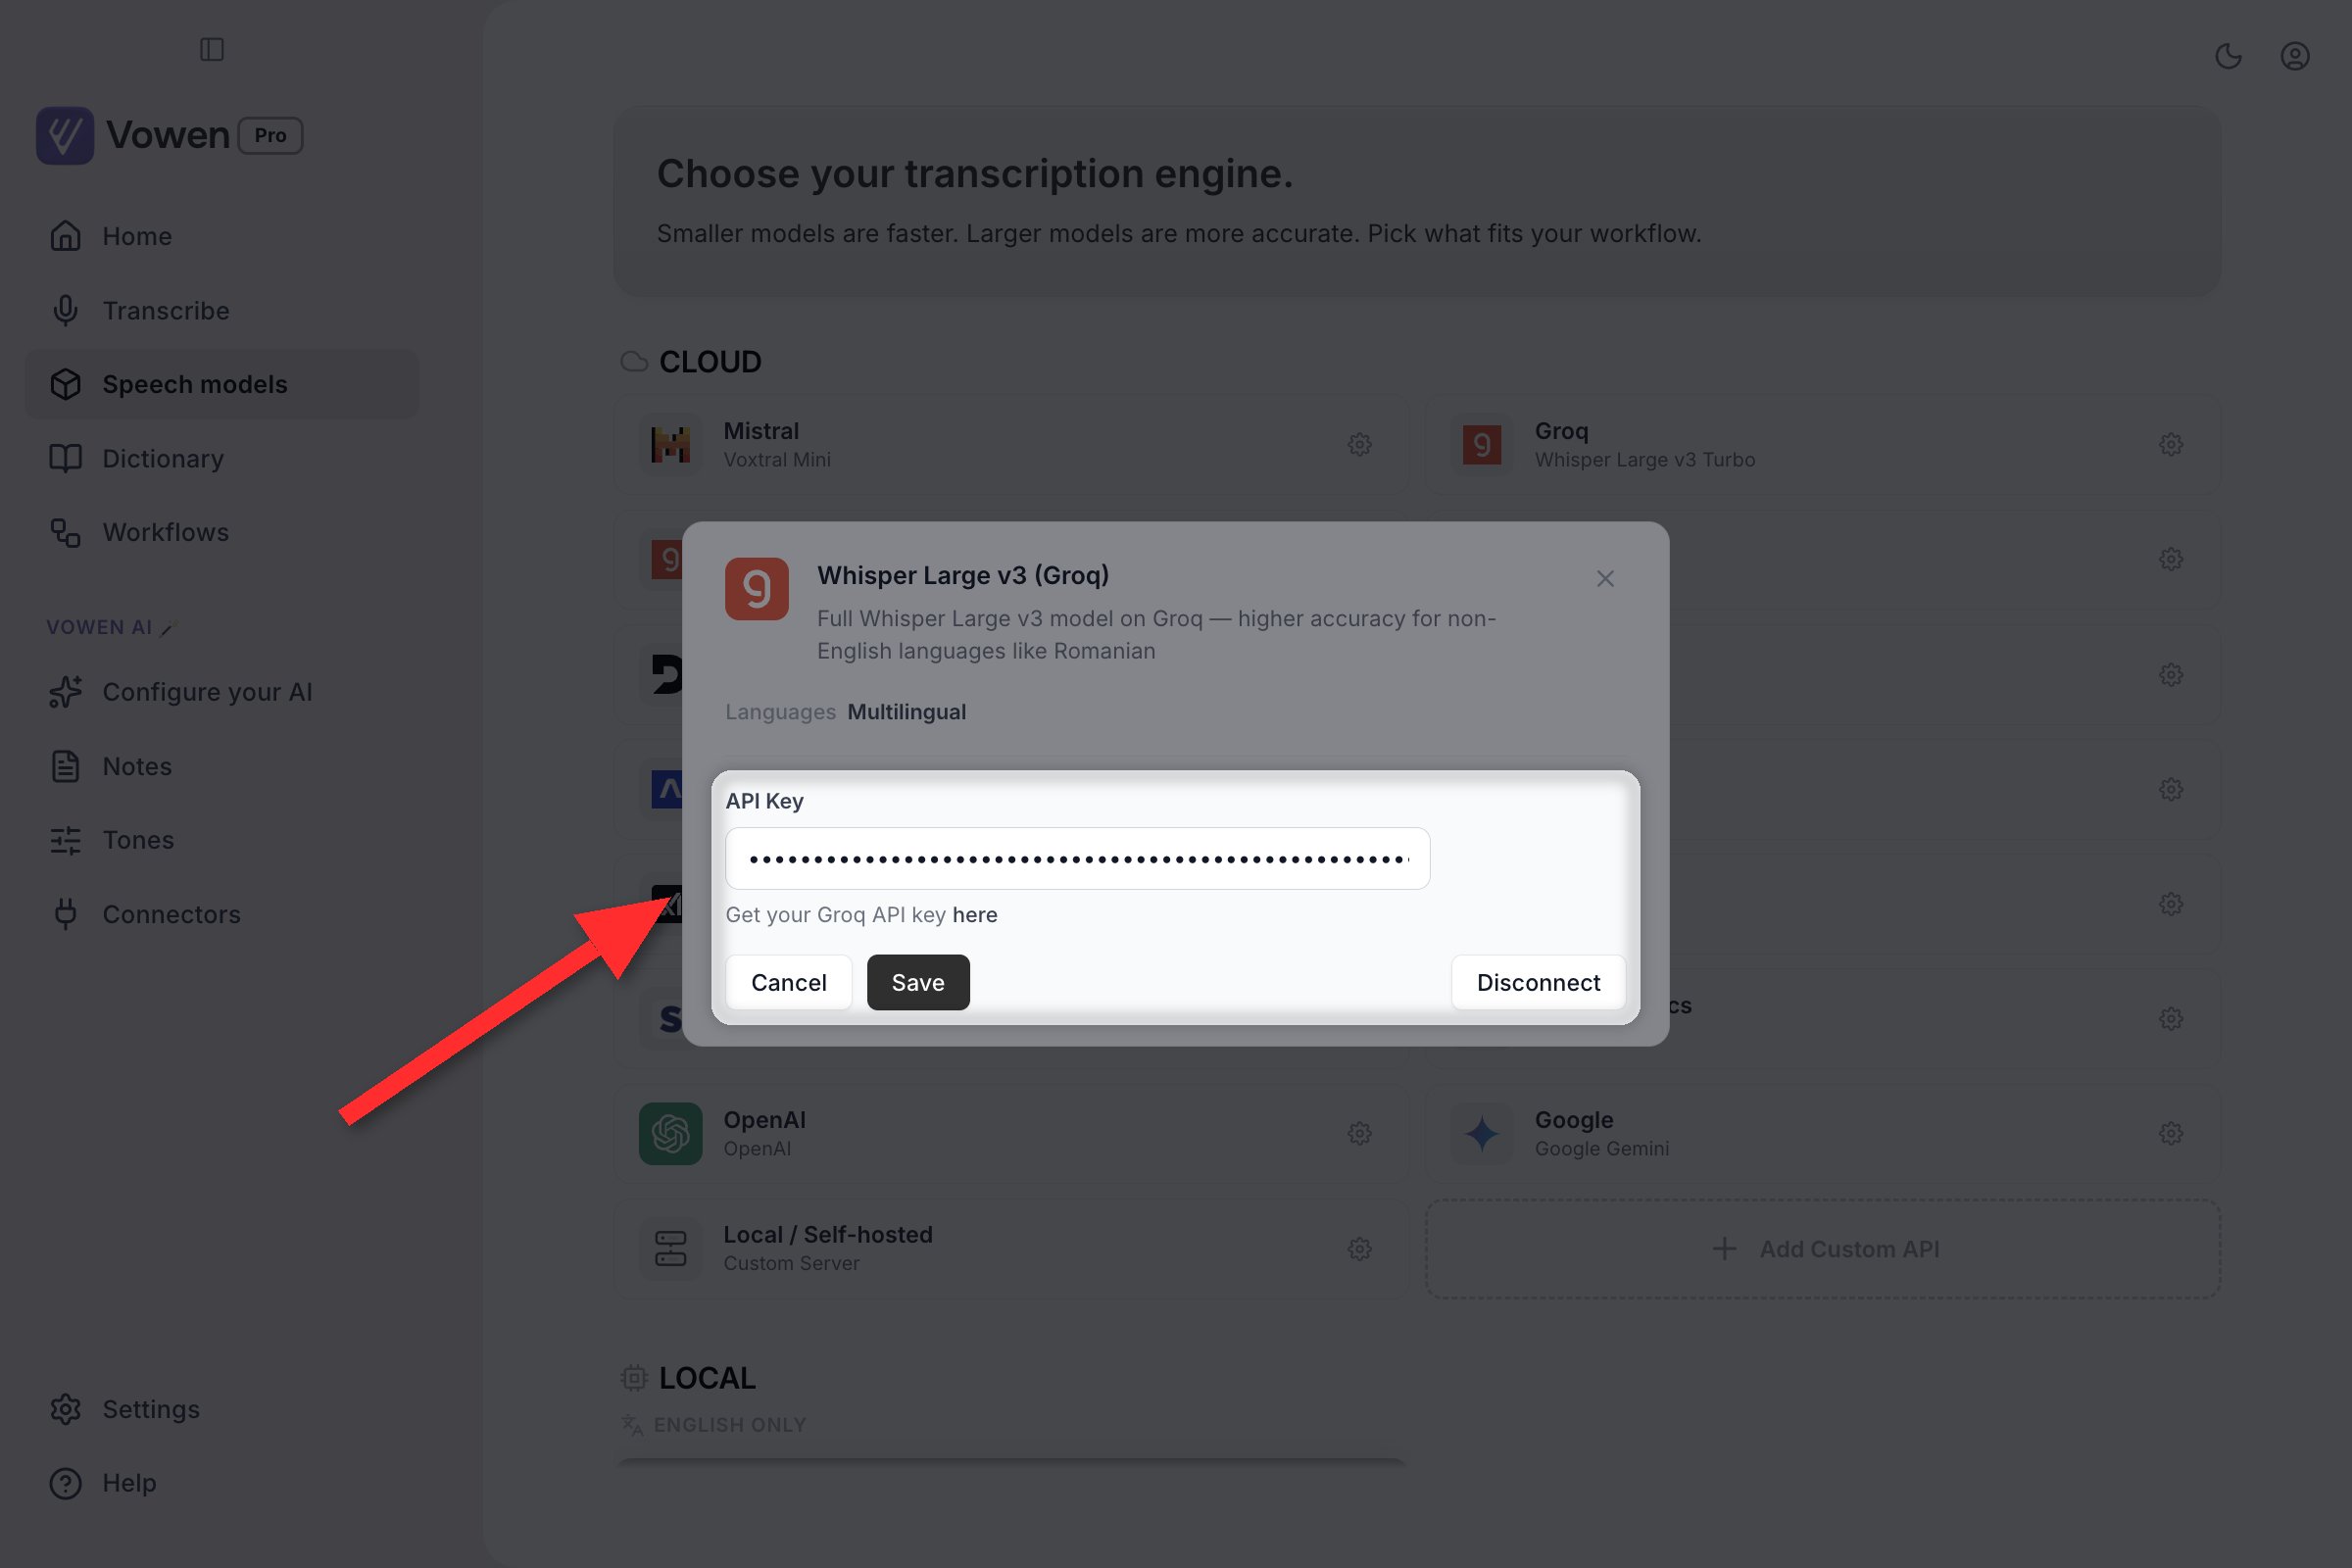
 Use the "Get your API key here" link to open the provider's dashboard, generate a key, and paste it in.
 The model becomes your active model immediately. You can connect as many providers as you like and switch between them at any time, including from the tray menu.
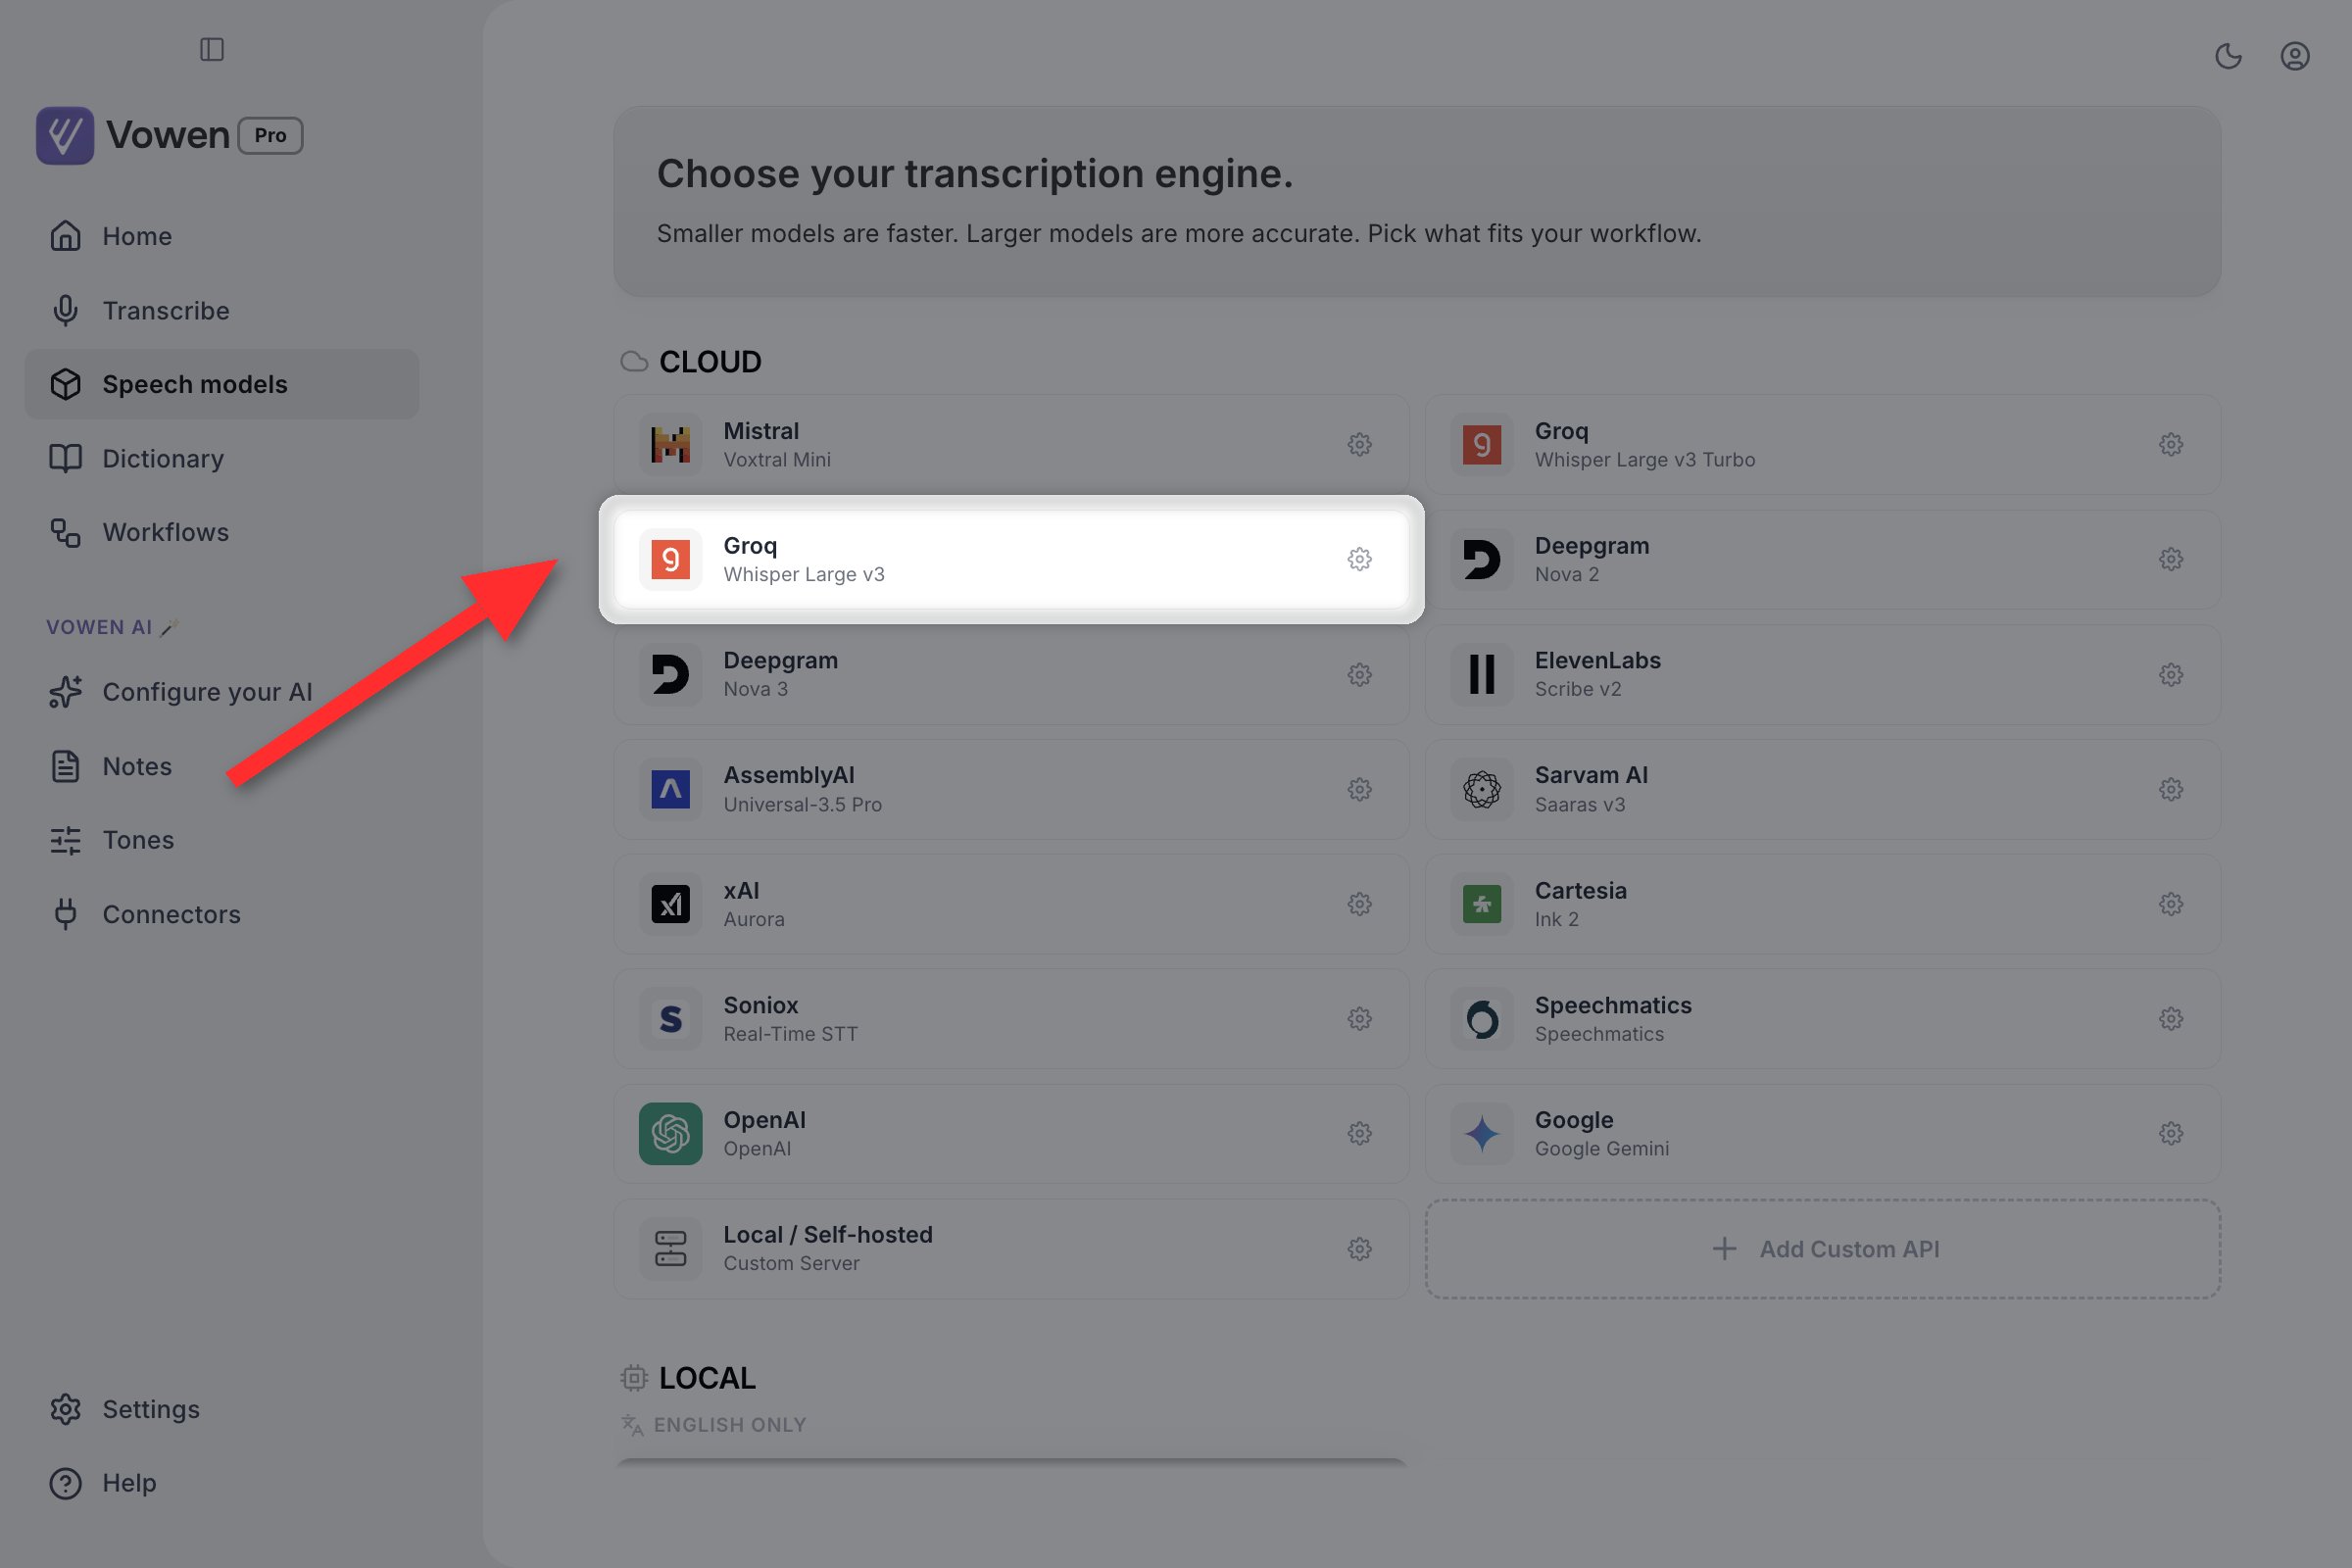 Groq is the most popular choice among Vowen users. It is fast, accurate, and its free tier covers most daily use.
### Per-model options
Two providers expose extra controls in the same panel where you paste the API key.
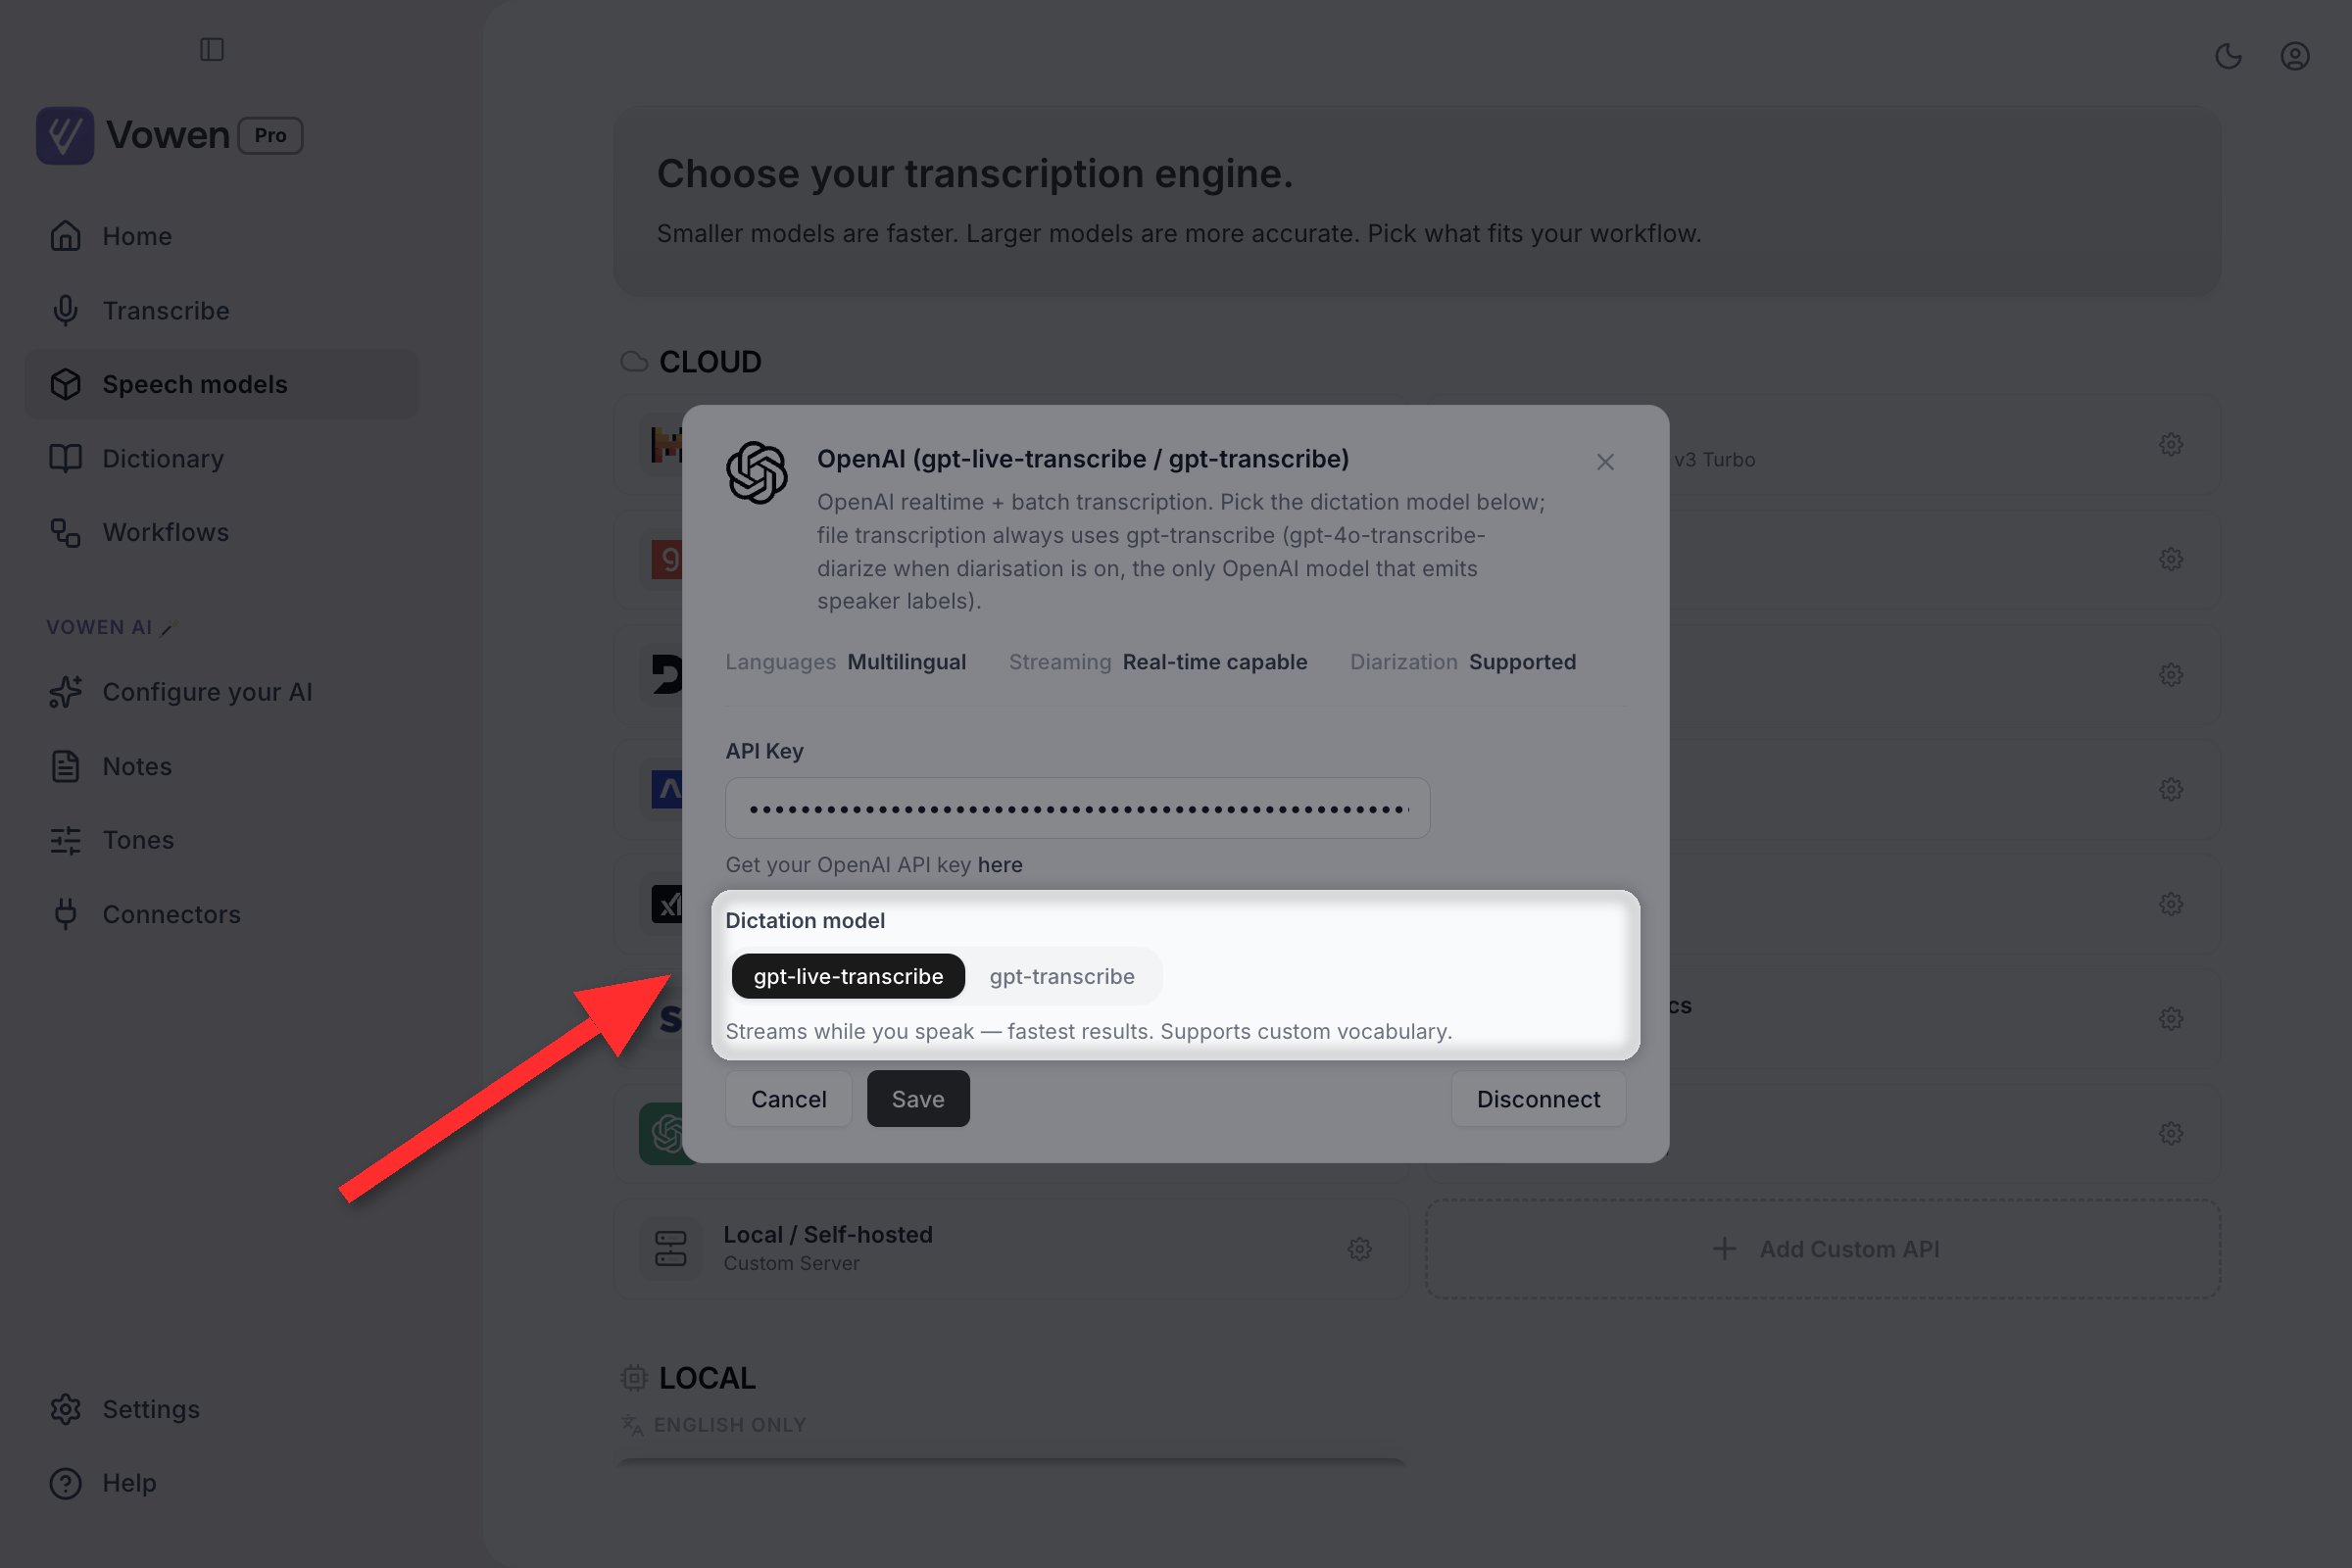
For OpenAI, **Dictation model** is a two-way toggle:
| Option | Behavior |
| - | - |
| `gpt-live-transcribe` | Streams while you speak. Fastest results. Supports custom vocabulary. |
| `gpt-transcribe` | Transcribes after you stop speaking. Slightly slower, cheaper per minute. Supports custom vocabulary. |
This affects dictation only. File transcription always uses `gpt-transcribe`.
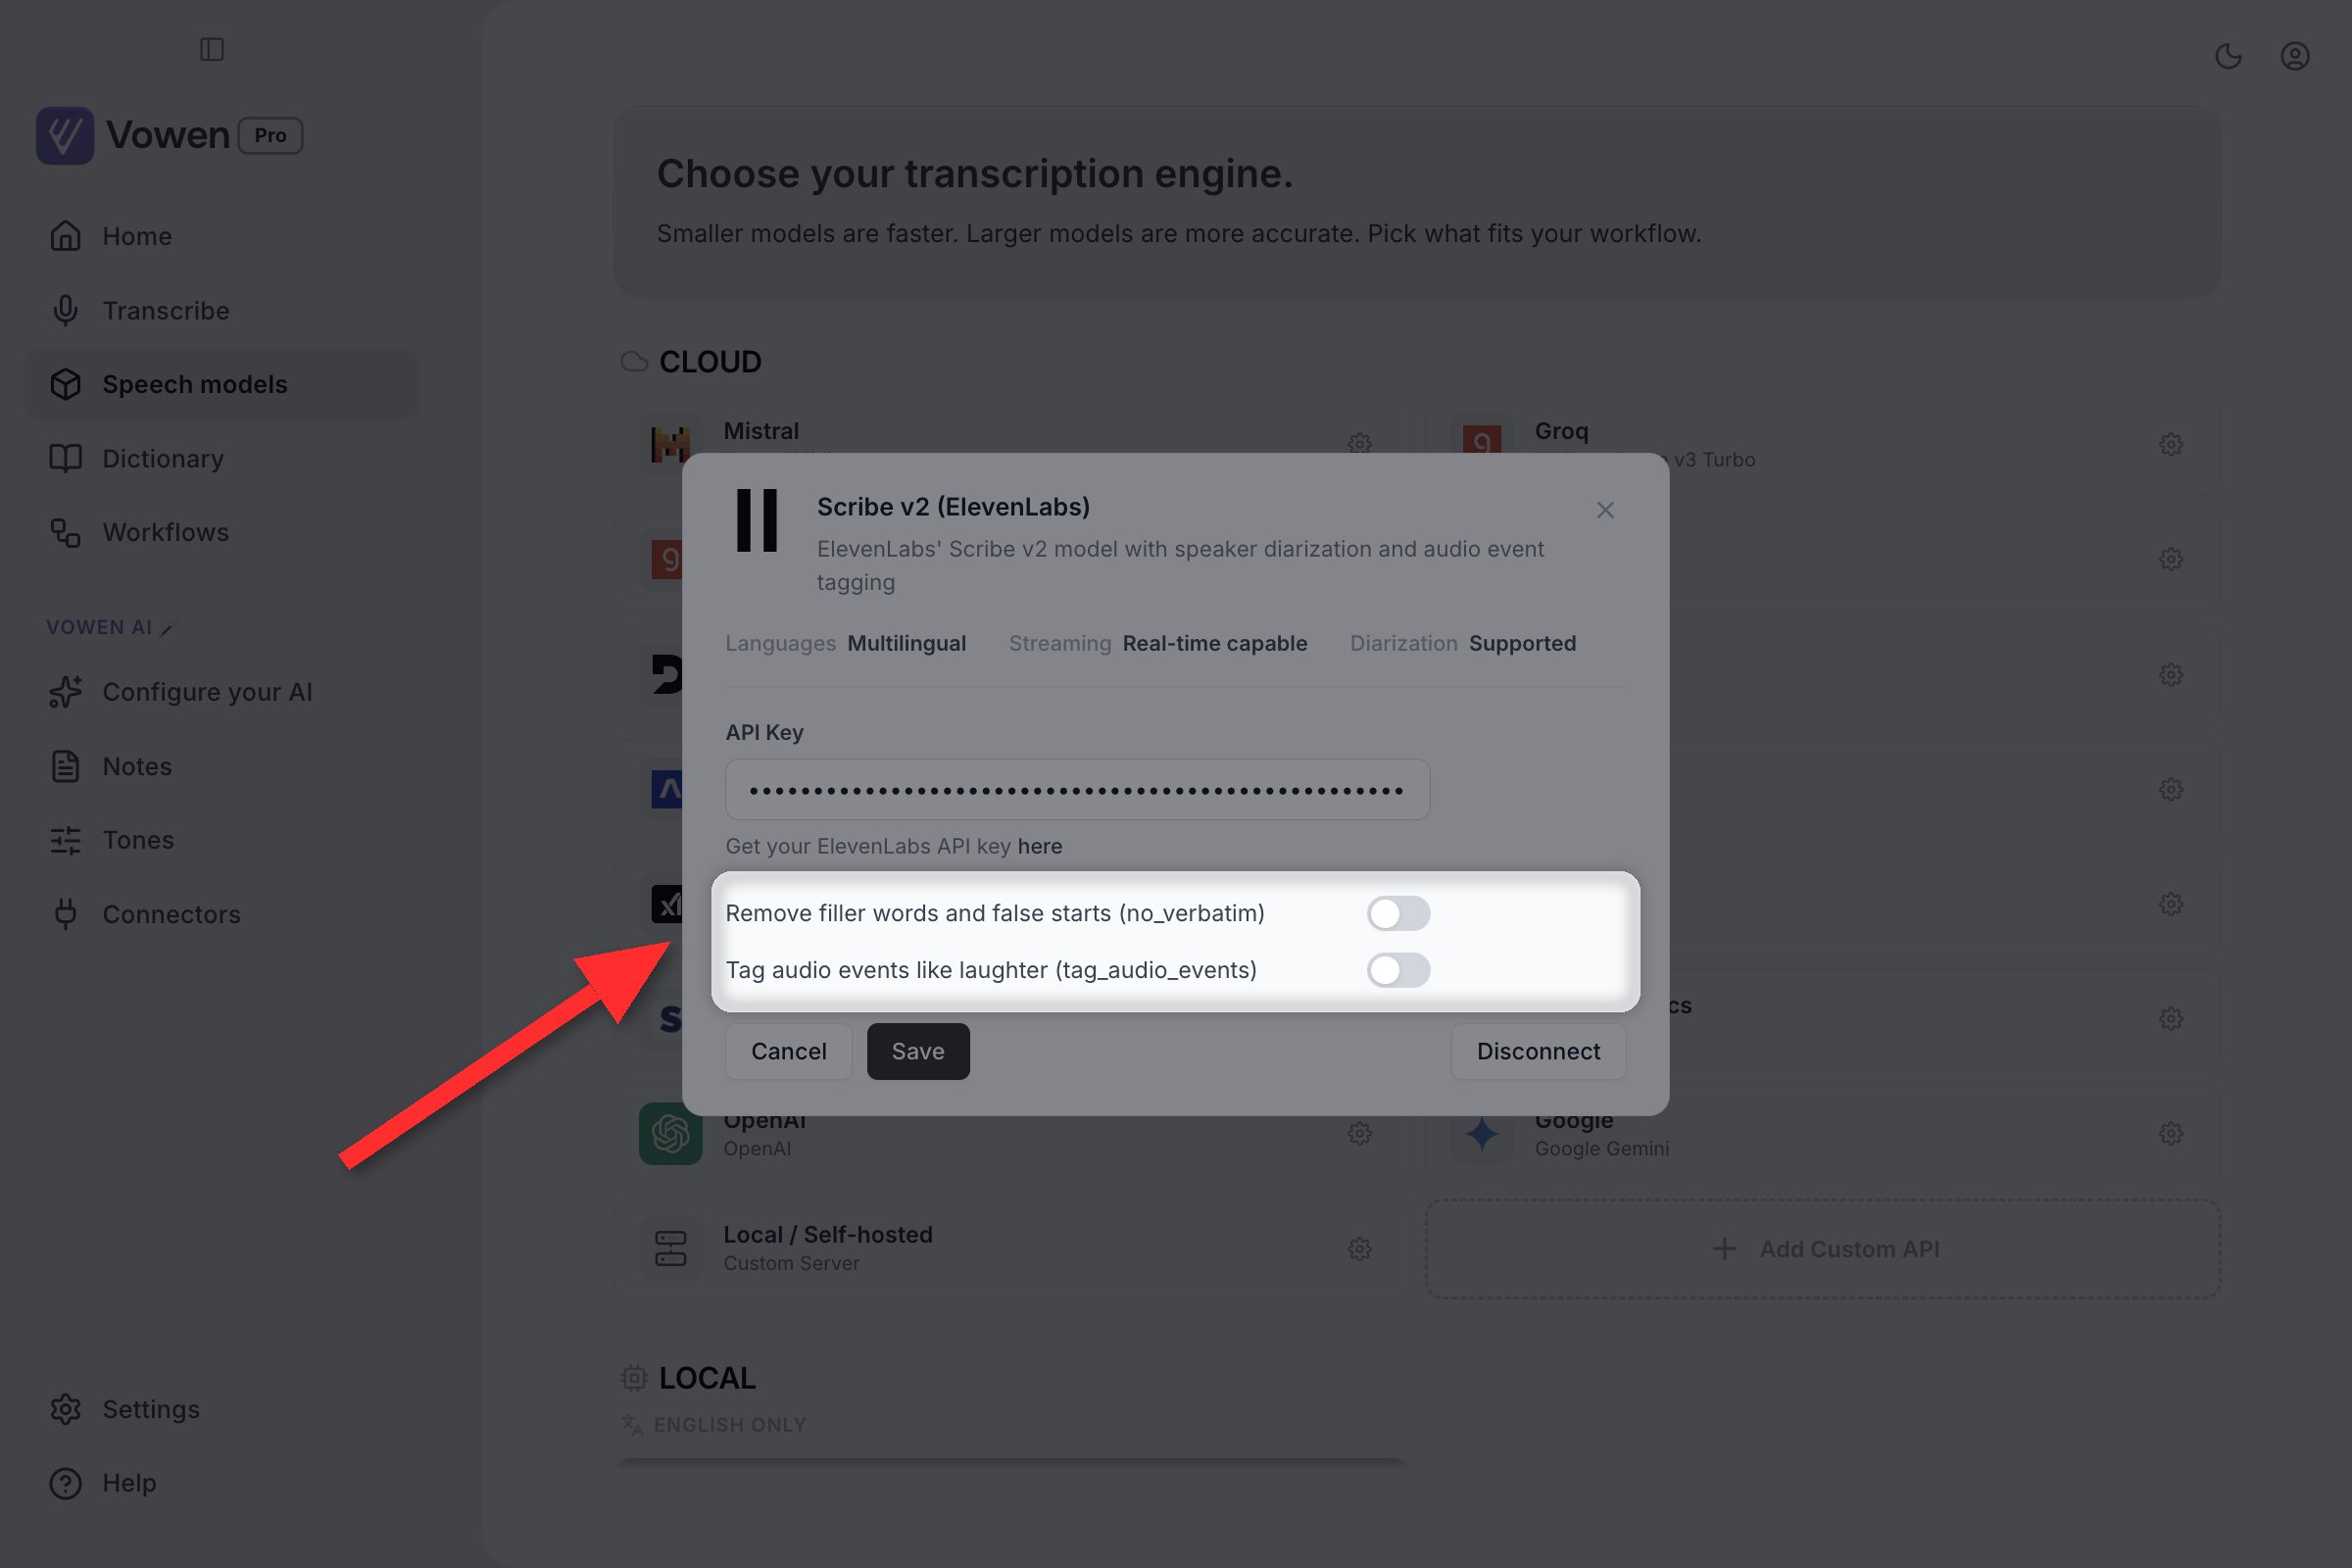
 **ElevenLabs Scribe v2** has two toggles, both off by default:
| Toggle | What it does |
| - | - |
| Remove filler words and false starts | ElevenLabs cleans the transcript itself before returning it |
| Tag audio events like laughter | Non-speech events appear in the transcript |
 ## Custom speech servers
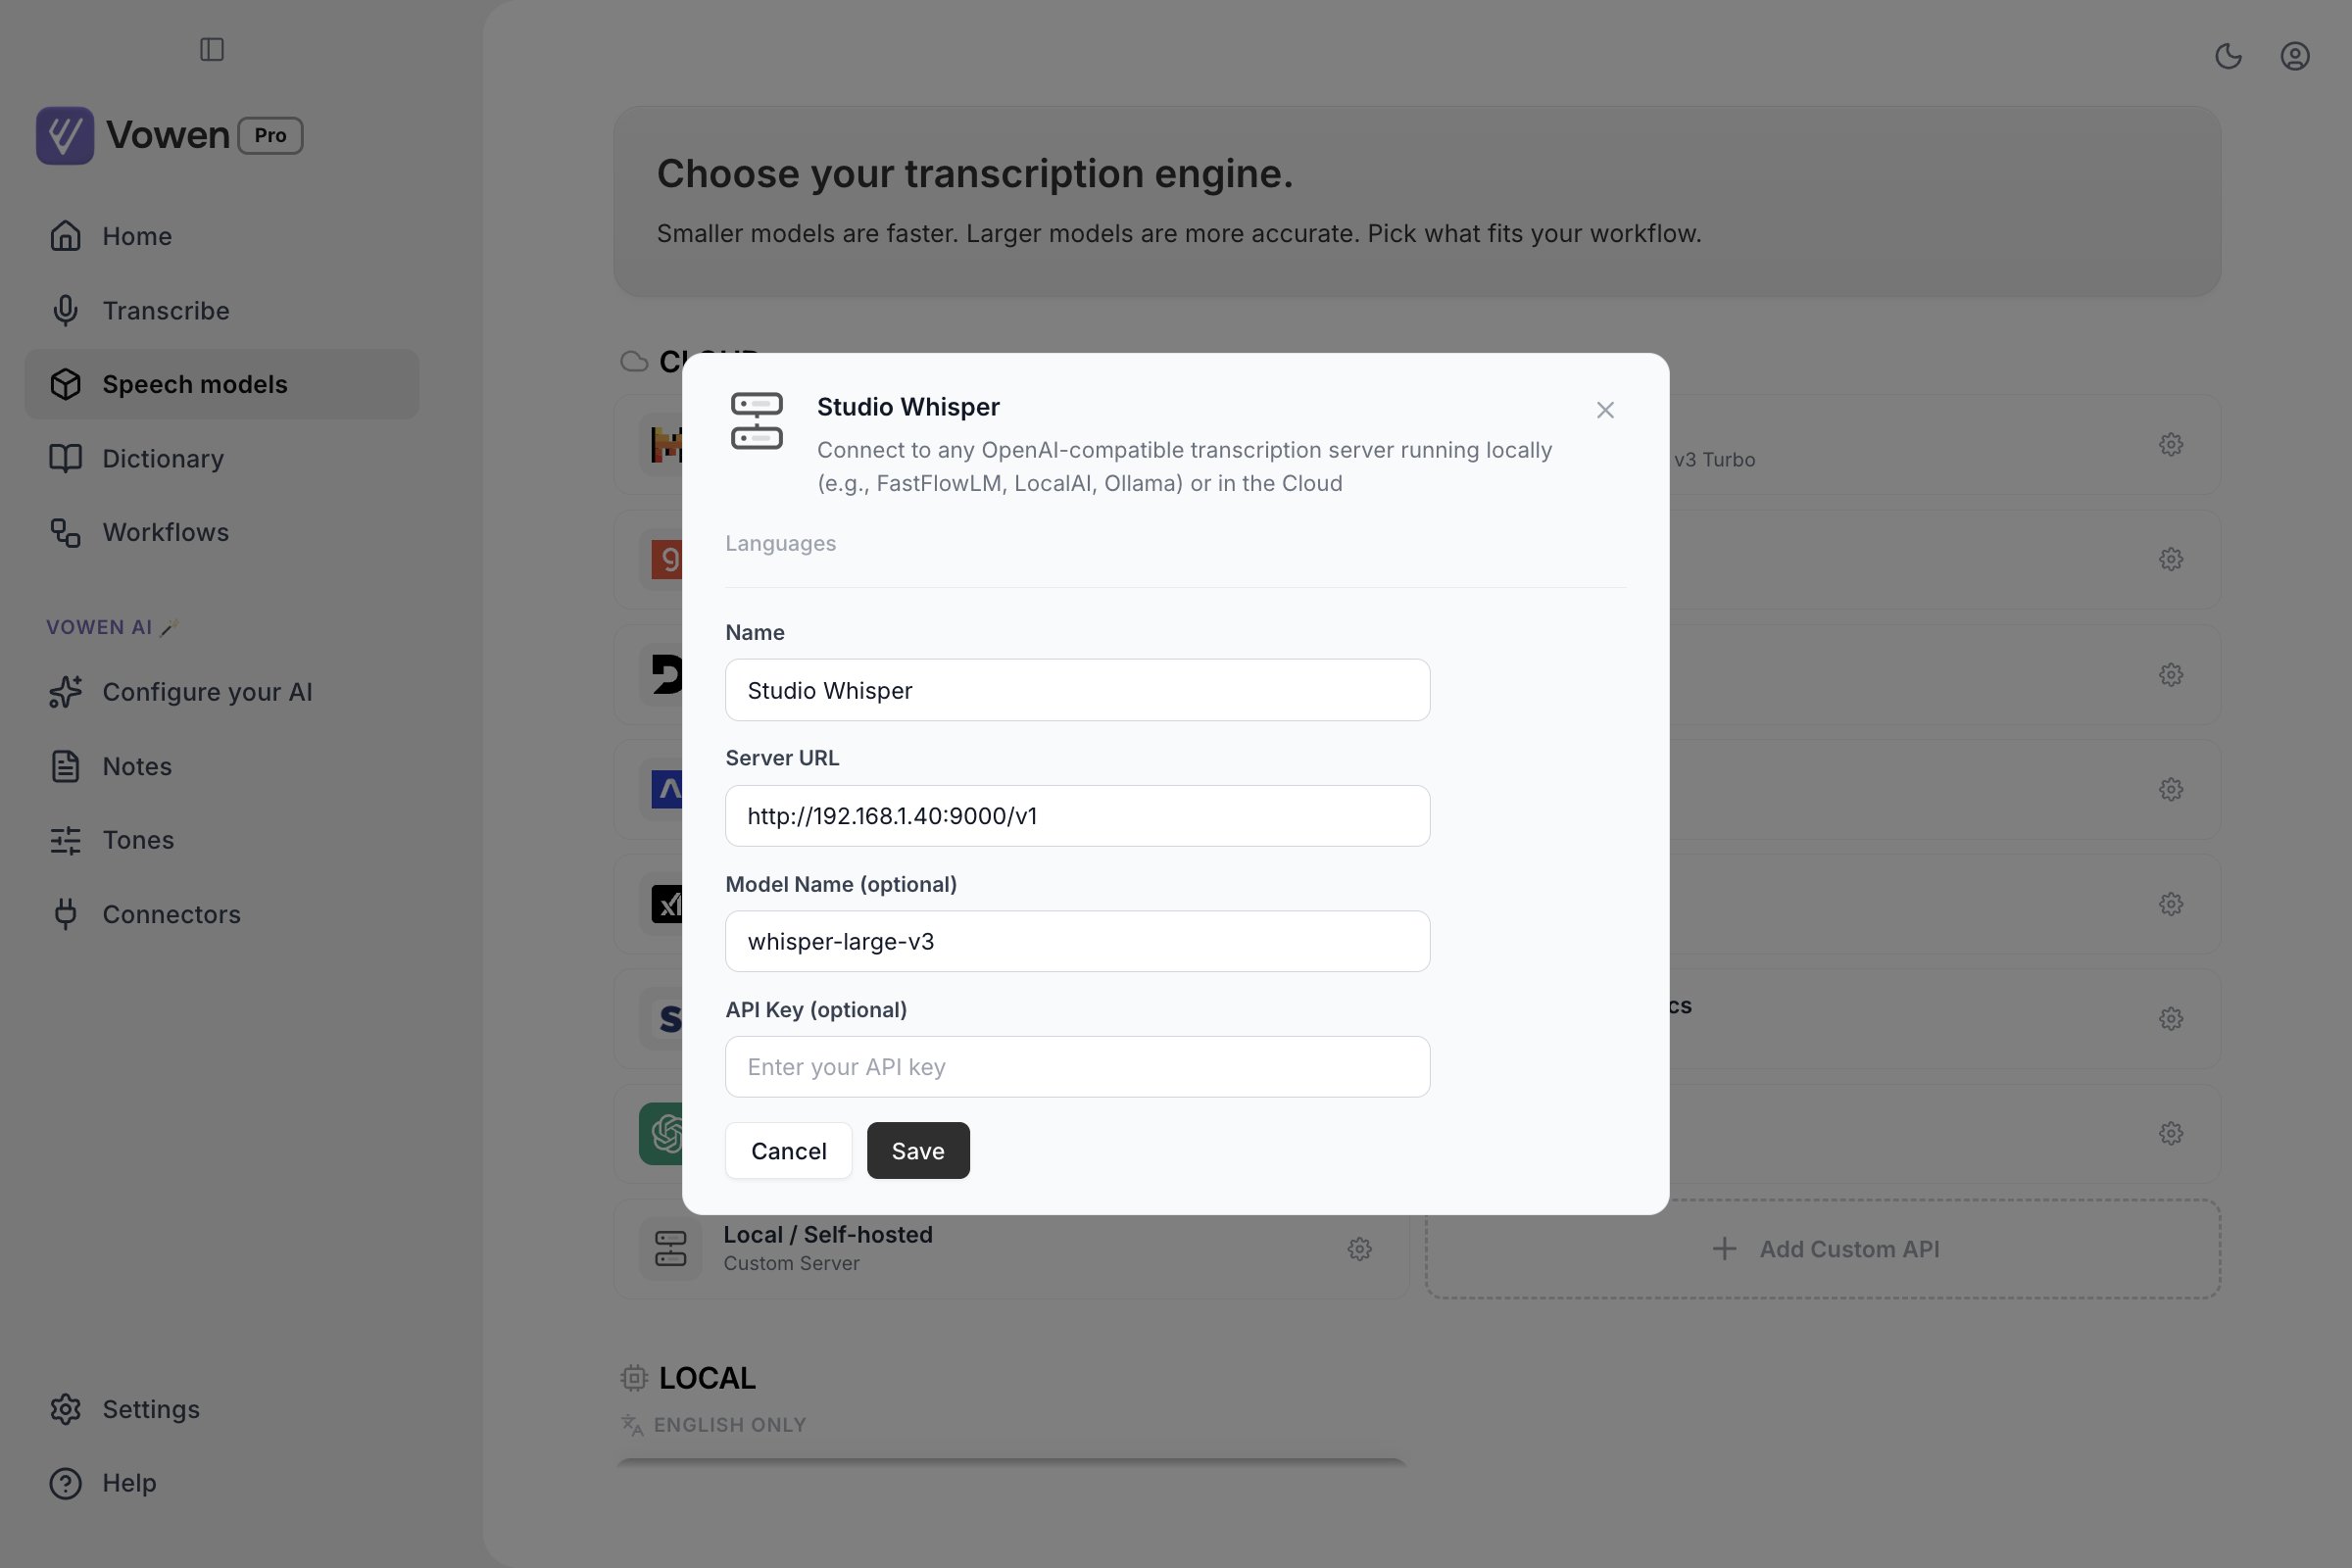
Point Vowen at any **OpenAI-compatible transcription endpoint**: a local whisper.cpp server, LocalAI, Ollama, FastFlowLM, a vLLM Whisper deployment, or a hosted service that speaks the same API.
A custom server needs a **Server URL**. A **Model Name** and an **API Key** are both optional; leave them blank when your server does not require them. Vowen checks that the URL is reachable before saving, so a typo fails immediately instead of surfacing at your next dictation.
Once saved, a custom server behaves like any other cloud model: it renders as its own card on the Speech models page, appears in every model picker, and can be selected from the tray.
 | Plan | Custom servers |
| - | - |
| Free | One server, using the built-in **Custom Server** card |
| Pro | Unlimited servers, each with a name you choose |
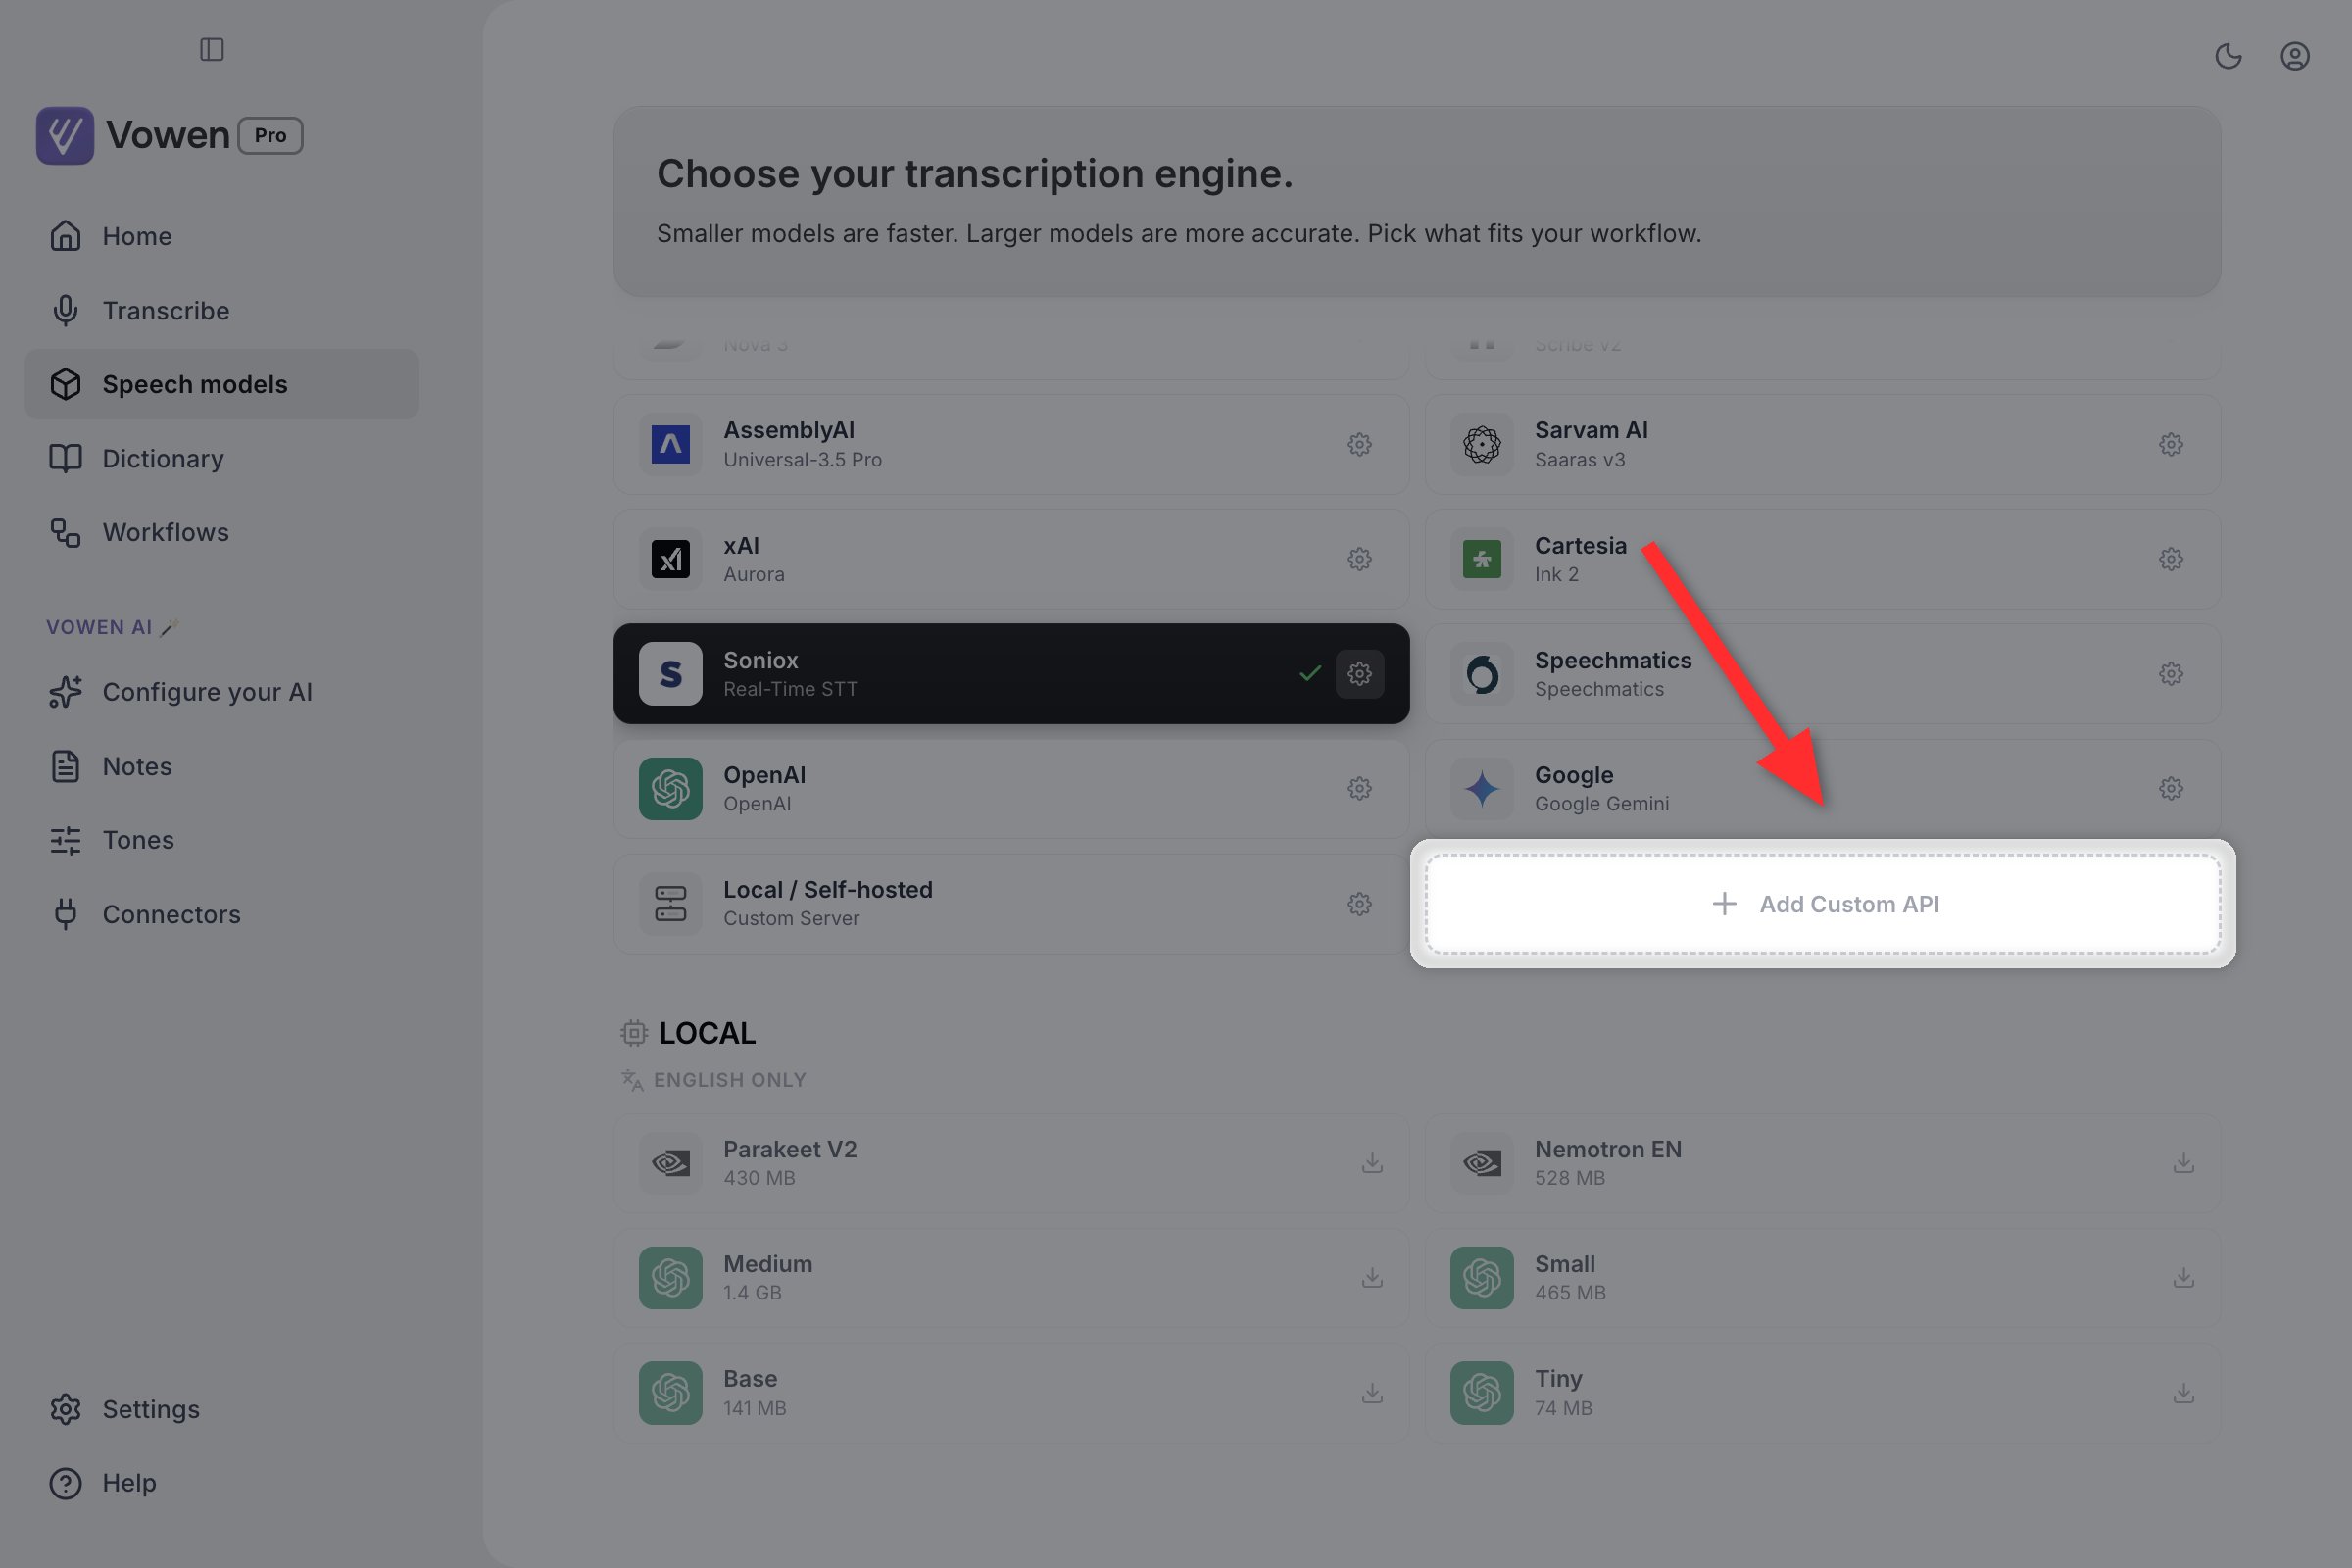
Adding a **second and further** custom server is a Pro feature. Use **Add Custom API** at the end of the cloud section. Free users keep the single original slot.
Custom servers receive your Dictionary terms the same way Groq does, as a hint. It helps, but less than an engine that uses your Dictionary directly.
## Speaker identification
Not every model can label who said what. These can, for pre-recorded audio and meeting notes:
**Cloud:** Nova 2 and Nova 3 (Deepgram), Scribe v2 (ElevenLabs), Universal-3.5 Pro (AssemblyAI), Voxtral Mini (Mistral), Aurora (xAI), Speechmatics, OpenAI, Gemini.
**Local, on macOS and Windows:** Parakeet V2, Parakeet V3, and every Whisper model. Groq's two Whisper models also qualify, because Vowen runs the same on-device speaker pipeline over their output.
Nemotron, Parakeet Japanese, Parakeet Mandarin, Cartesia Ink 2, Saaras v3 and custom servers do not offer speaker labels.
Speaker identification is a Pro feature. Full detail in [Diarization](/meeting-notes/diarization).
## Real-time preview
Live text under the recording indicator needs a streaming-capable model. Every cloud model in the table above except the two Groq entries and custom servers can stream. Locally, Parakeet V2, Parakeet V3, Nemotron EN and Nemotron Multilingual stream on macOS; Parakeet streaming is not available on Windows.
Turn it on in **Settings > Recording > Real-time transcription preview**. The row is greyed out until your active model can stream.
## GPU acceleration (Windows)
If you have an NVIDIA GPU, Vowen can download a CUDA acceleration module that dramatically speeds up local Whisper transcription.
* **Windows only.** macOS is already accelerated and needs nothing extra; Linux is not supported.
* Requires an **RTX 2000 series or newer** NVIDIA GPU.
* The download is about **631 MB**. No separate CUDA toolkit install is needed.
The card only appears on the Speech models page when Vowen detects a supported GPU. Download it, restart Vowen, and even Large v3 responds in a couple of seconds.
## Local or cloud
| Factor | Local | Cloud |
| - | - | - |
| Privacy | Audio never leaves your device | Audio is sent to the provider |
| Speed (macOS) | Very fast with Parakeet or Nemotron | Fast |
| Speed (Windows) | Fast with Parakeet; slow for large Whisper without a GPU | Fast |
| Accuracy | Good to excellent | Excellent |
| Internet | Not required | Required |
| Cost | Free | Free tier or paid API |
| Custom vocabulary | Whisper (Small and up) only | Used well by most providers |
| Languages | 99 (Whisper), 31 (Nemotron), 25 (Parakeet V3) | Varies by provider |
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.