> ## Documentation Index
> Fetch the complete documentation index at: https://docs.vowen.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Tips for Better Accuracy
> Get the most accurate transcriptions from Vowen.
The fastest path to high accuracy is pairing a good speech model with [AI Enhancement](/ai-features/ai-enhancement), then adding the words you say most to your [Dictionary](/features/dictionary). The model handles fast or accented speech, AI Enhancement cleans the rest, and the Dictionary keeps domain terms spelled correctly. Check first whether your model applies vocabulary at all. See [How vocabulary actually reaches each model](#how-vocabulary-actually-reaches-each-model).
## Choose the right model
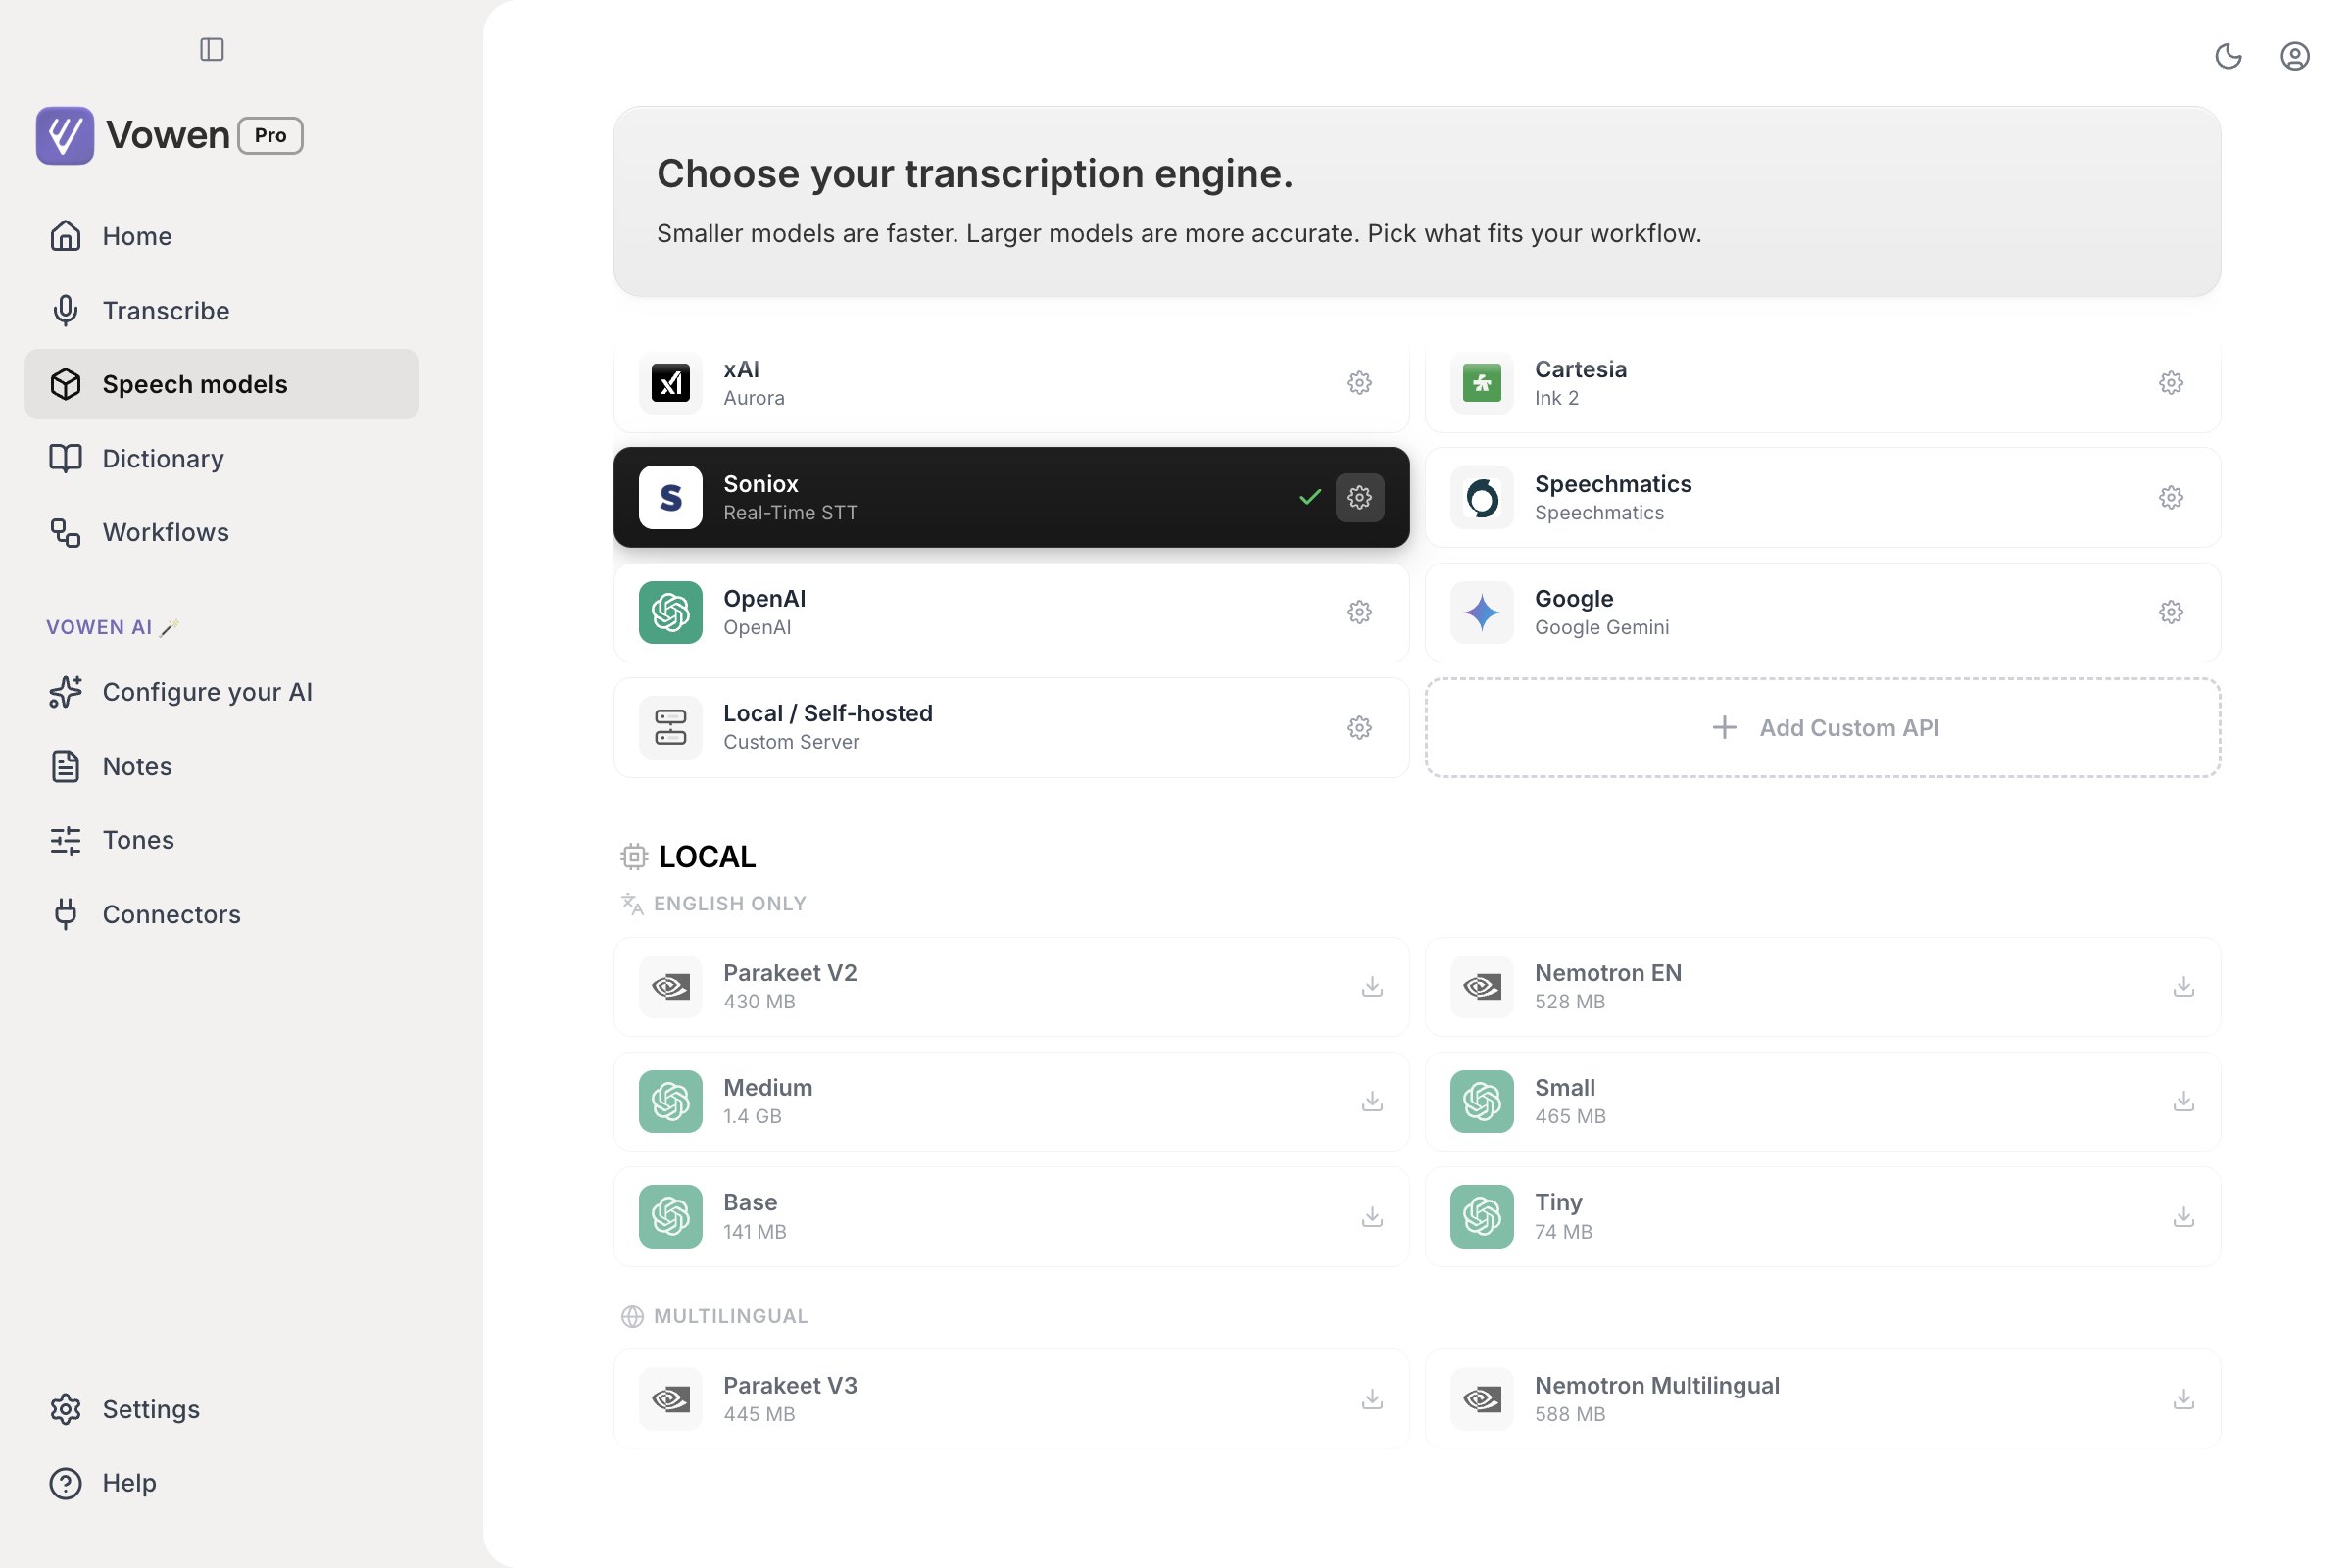
Model choice is the single biggest factor in accuracy. See the [Models guide](/transcription/models) for the full comparison.
Rules of thumb:
* **English, offline:** Parakeet V2 is the default and is genuinely good. Nemotron EN (macOS) matches it and gives a punctuated live preview.
* **Professional work:** Whisper Large v3 Turbo locally, or a cloud model.
* **Non-English:** Parakeet V3 for European languages, Whisper Large v3 on Groq for everything else.
* **Fast or accented speech:** cloud models generally cope better than small local ones.
 ## Microphone tips
* **Use a dedicated microphone** when possible. Even basic earbuds beat a laptop mic at arm's length.
* **Minimize background noise.** Vowen has noise suppression, but a quieter room helps more.
* **Keep a consistent distance** from your microphone.
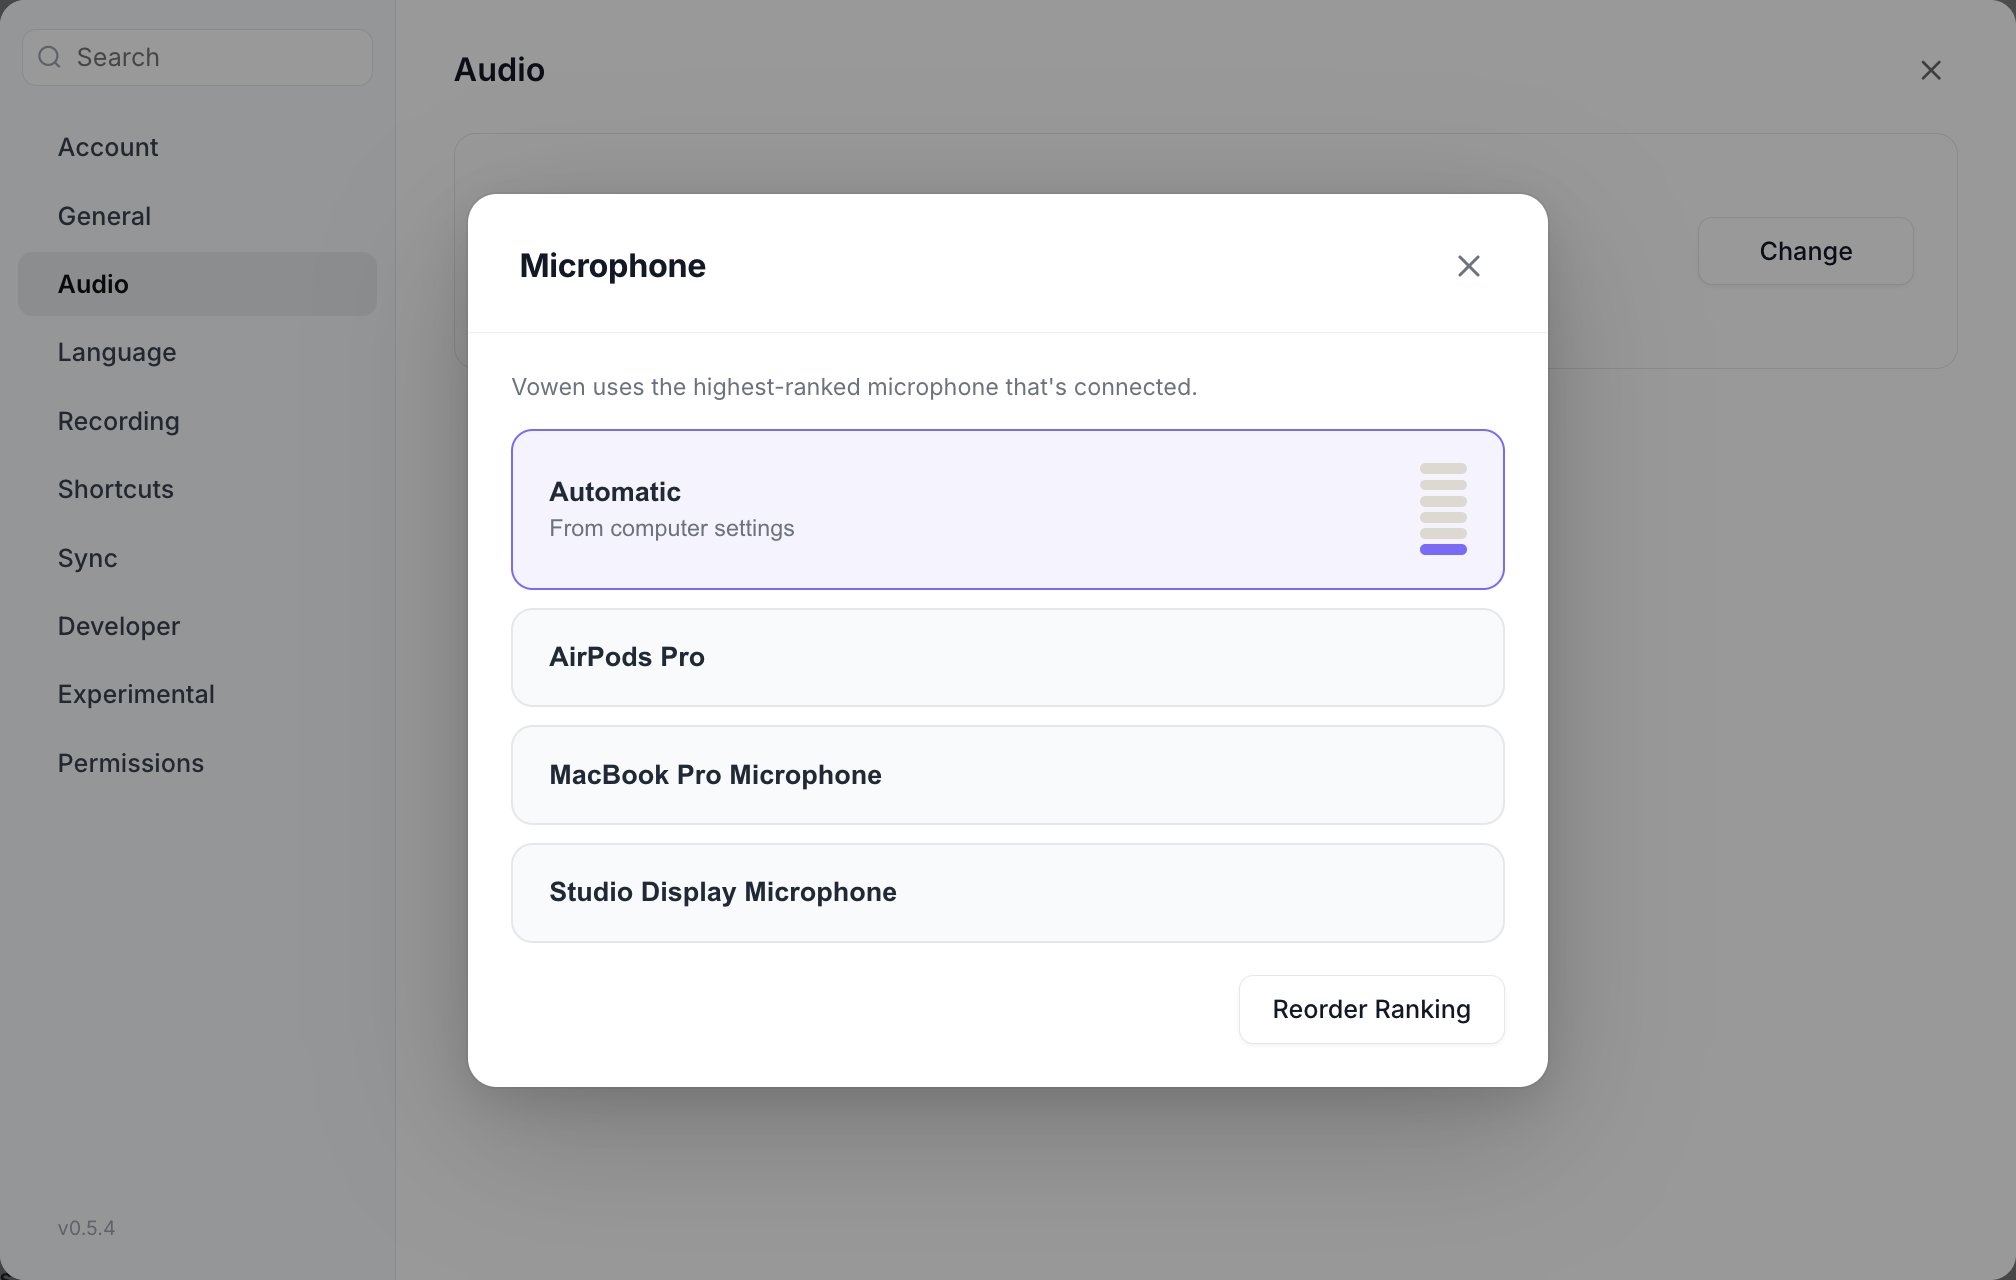
* **Check your input device** in **Settings > Audio** to make sure the right mic is selected.
 ## Speaking tips
* **Speak at a natural pace.** Rushing makes words blend together.
* **Pause briefly** before and after speaking so the first and last words are not clipped.
* **Enunciate** technical terms and unusual names.
* **Say punctuation explicitly** if you need it: "period", "comma", "new line". With AI enhancement, punctuation is added for you.
## Use your Dictionary
Add terms the model gets wrong: product names, technical jargon, proper nouns, acronyms, colleagues' names.
Click **Dictionary** in the left sidebar. It is a top-level page, not a settings tab.
Click **Add Word** in the toolbar and type the term as you want it spelled.
List the ways the recognizer gets it wrong: "cuber netties" for "Kubernetes", "github" for "GitHub". See [below](#mishearing-aliases).
Full guide: [Dictionary & Vocabulary](/features/dictionary).
### How vocabulary actually reaches each model
There is no single answer. Some engines steer recognition towards your terms and use your Dictionary well. Some take them only as a loose hint. Several take nothing at all, and on those your Dictionary does not affect transcription.
| Engine | Uses your Dictionary | Practical limit |
| - | - | - |
| Deepgram Nova 3 | Well | \~100 terms |
| Deepgram Nova 2 | Well | \~50 terms |
| AssemblyAI (files) | Well | Up to 1,000 terms, max 6 words each |
| AssemblyAI (dictation) | Well | 100 terms, max 6 words and 50 characters each |
| ElevenLabs Scribe v2 (files) | Well | 100 terms, max 5 words and 49 characters each |
| ElevenLabs Scribe v2 (dictation) | Well | 50 terms, max 5 words and 20 characters each |
| Speechmatics | Well | Up to 1,000 terms, max 6 words each |
| xAI Aurora | Well | 100 terms, max 50 characters each |
| Mistral Voxtral | Well | 100 terms. Spaces become underscores |
| Soniox | Well | About 6,000 tokens' worth of terms |
| Cartesia Ink 2 (dictation) | Well | 100 terms, 1,200 characters total |
| OpenAI `gpt-live-transcribe` / `gpt-transcribe` | Well | — |
| Gemini (files) | Weakly, as a hint | 100 terms |
| Groq Whisper | Weakly, as a hint | About 180 tokens' worth of terms |
| Local Whisper: Small, Medium, Large v3, Large v3 Turbo | Weakly, as a hint | About 180 tokens' worth of terms |
| Custom speech server | Weakly, as a hint | About 180 tokens' worth of terms |
| Sarvam Saaras v3 (dictation) | Weakly, as a hint | 50 terms |
The engines that get nothing:
| Engine | Why |
| - | - |
| **Parakeet** (all four models) | No vocabulary is applied at transcription time. |
| **Nemotron** (both models) | Same. Vocabulary never reaches the engine. |
| **Sarvam Saaras v3, file transcription** | Sarvam applies your terms during live dictation only. Files get nothing. |
| **Cartesia, file transcription** | Cartesia applies your terms during live dictation only. |
| **OpenAI `gpt-4o-transcribe-diarize`** | The only OpenAI model that emits speaker labels takes no vocabulary at all. Turning on speaker identification drops your vocabulary for that run. |
| **Gemini Live (dictation)** | Live dictation ignores your terms. Only Gemini file transcription applies them. |
| **Local Whisper Tiny and Base** | These models cannot act on vocabulary reliably, so Vowen skips them entirely. |
If your model is **Parakeet or Nemotron**, adding words to your Dictionary will not change what the recognizer hears. Your entries still work as [mishearing corrections](#mishearing-aliases) and [Threads](/features/threads), which are applied to the text afterwards. The recognition half does nothing. To influence recognition itself, switch to Whisper Small or larger, or to a cloud model from the table above.
When your list is longer than a provider's cap, Vowen does not cut it alphabetically. Terms are ranked by how often you have said them, then by how recently, so the words that matter to you survive the trim.
### Mishearing aliases
A Dictionary entry biases the recognizer, which is a hint, not a guarantee. A **mishearing** is the deterministic half. It is an exact phrase that gets rewritten to the entry's correct spelling after transcription, every time.
Open any Dictionary word and list the forms you keep seeing:
| Word | Mishearings |
| - | - |
| Kubernetes | cuber netties, cooper netties |
| GitHub | github, git hub |
| PostgreSQL | postgres QL, post gray sequel |
Matching ignores case, so listing `github` under `GitHub` fixes capitalization alone. This works with **every** model, including Parakeet and Nemotron, because it runs on the text after transcription.
### Auto-learning from your corrections
Auto-add to Dictionary is a Pro feature, marked Beta, available on macOS and Windows. It also requires at least one AI provider to be connected.
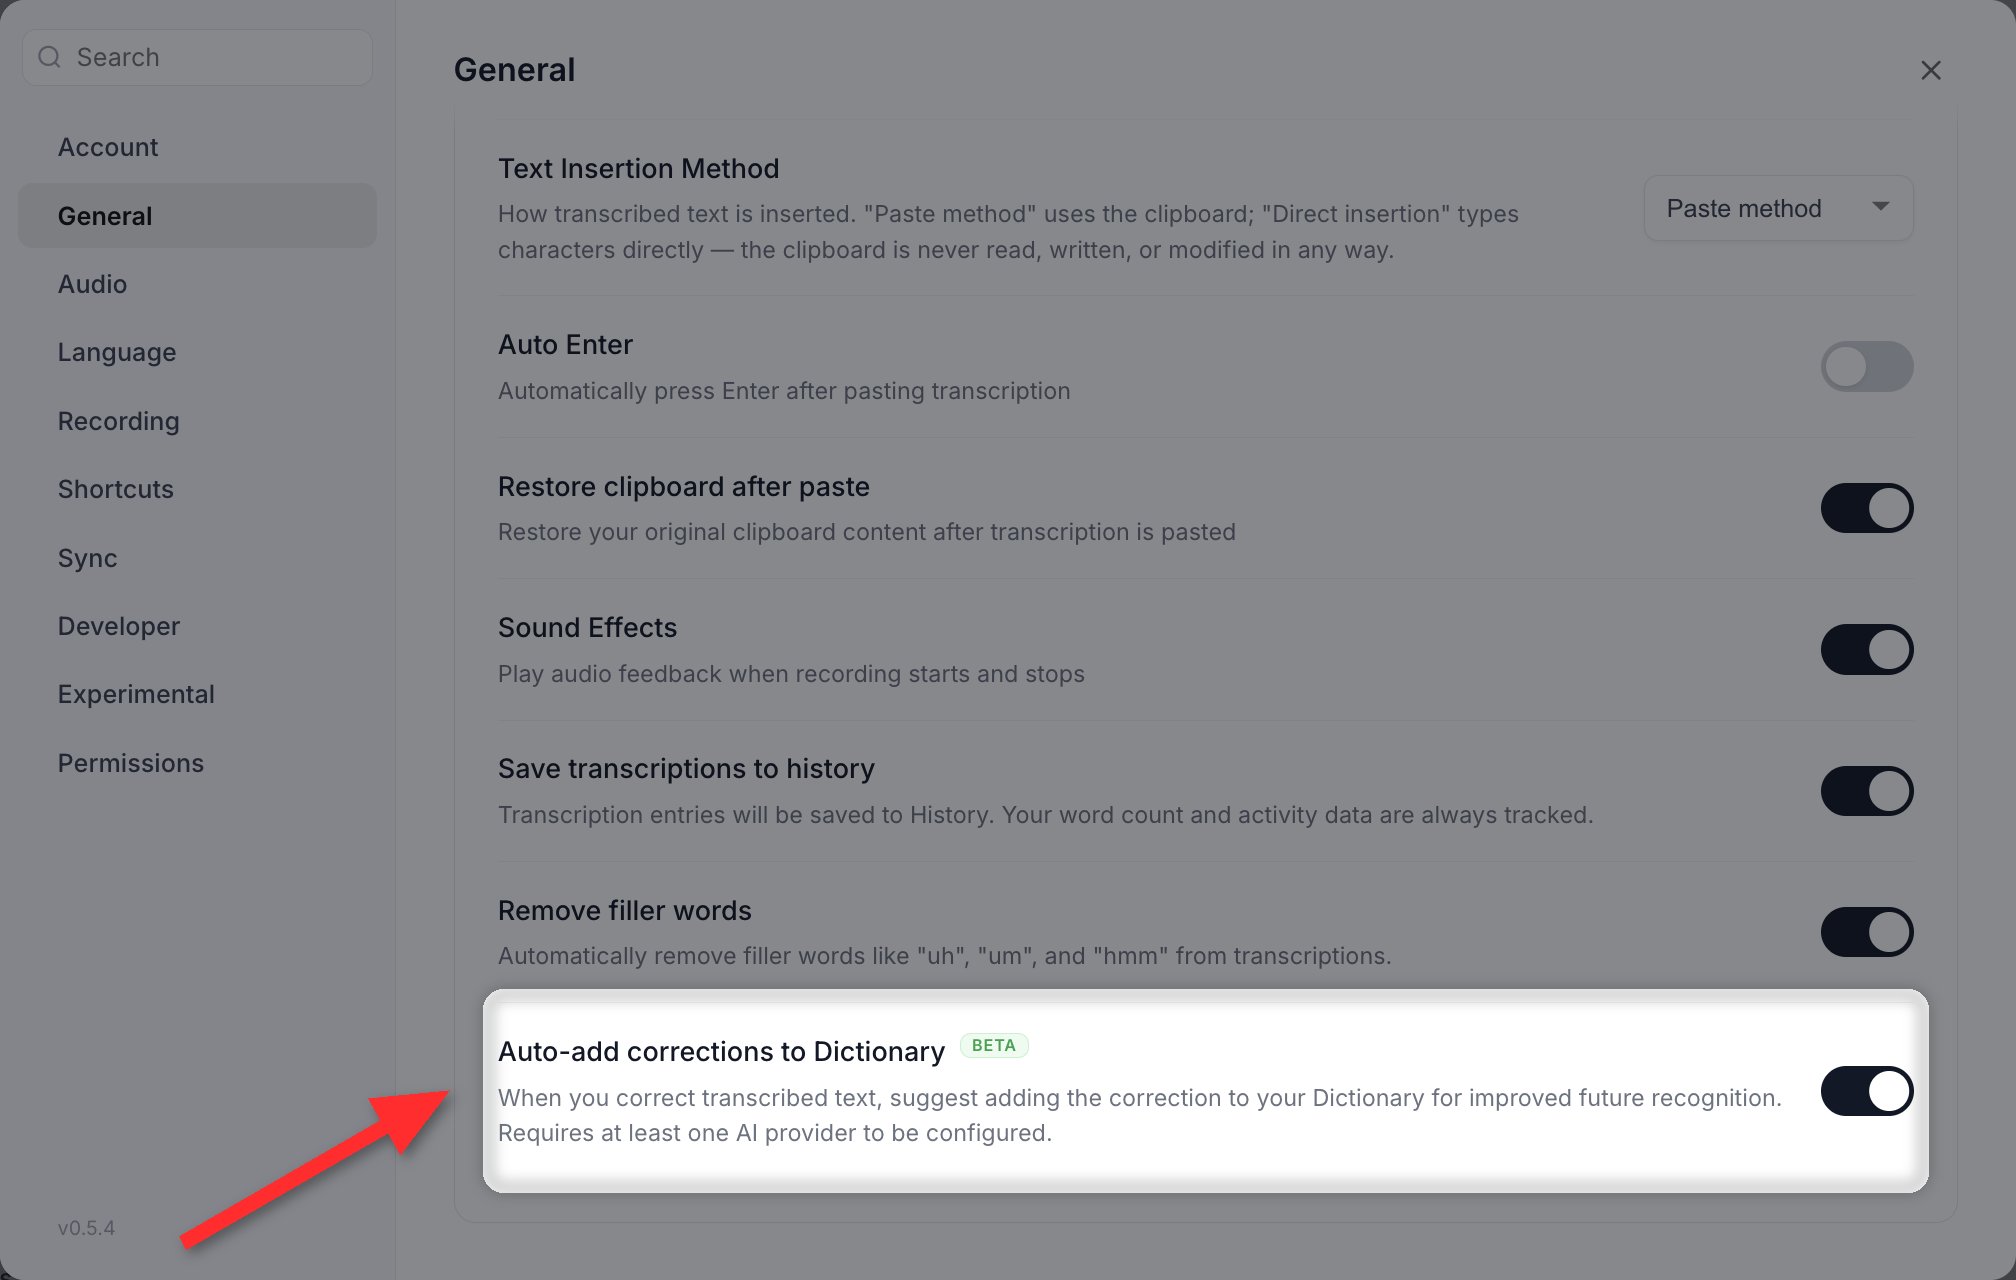
Turn on **Settings > General > Auto-add corrections to Dictionary** and Vowen watches what you fix by hand right after a dictation. When it sees you correcting the same recognizer mistake, it offers to add it for you.
The two routes have deliberately different evidence bars:
| Offer | Appears after | Why |
| - | - | - |
| **New word** | One sighting | A dictionary entry is only a hint, so a wrong one costs little. |
| **Mishearing** | Two sightings | A mishearing becomes a permanent find-and-replace on every future transcript, so it wants corroboration. |
Both routes ask before changing anything, and a refusal is remembered. Decline a suggestion and Vowen will not raise it again.
 ## Pass screen as context
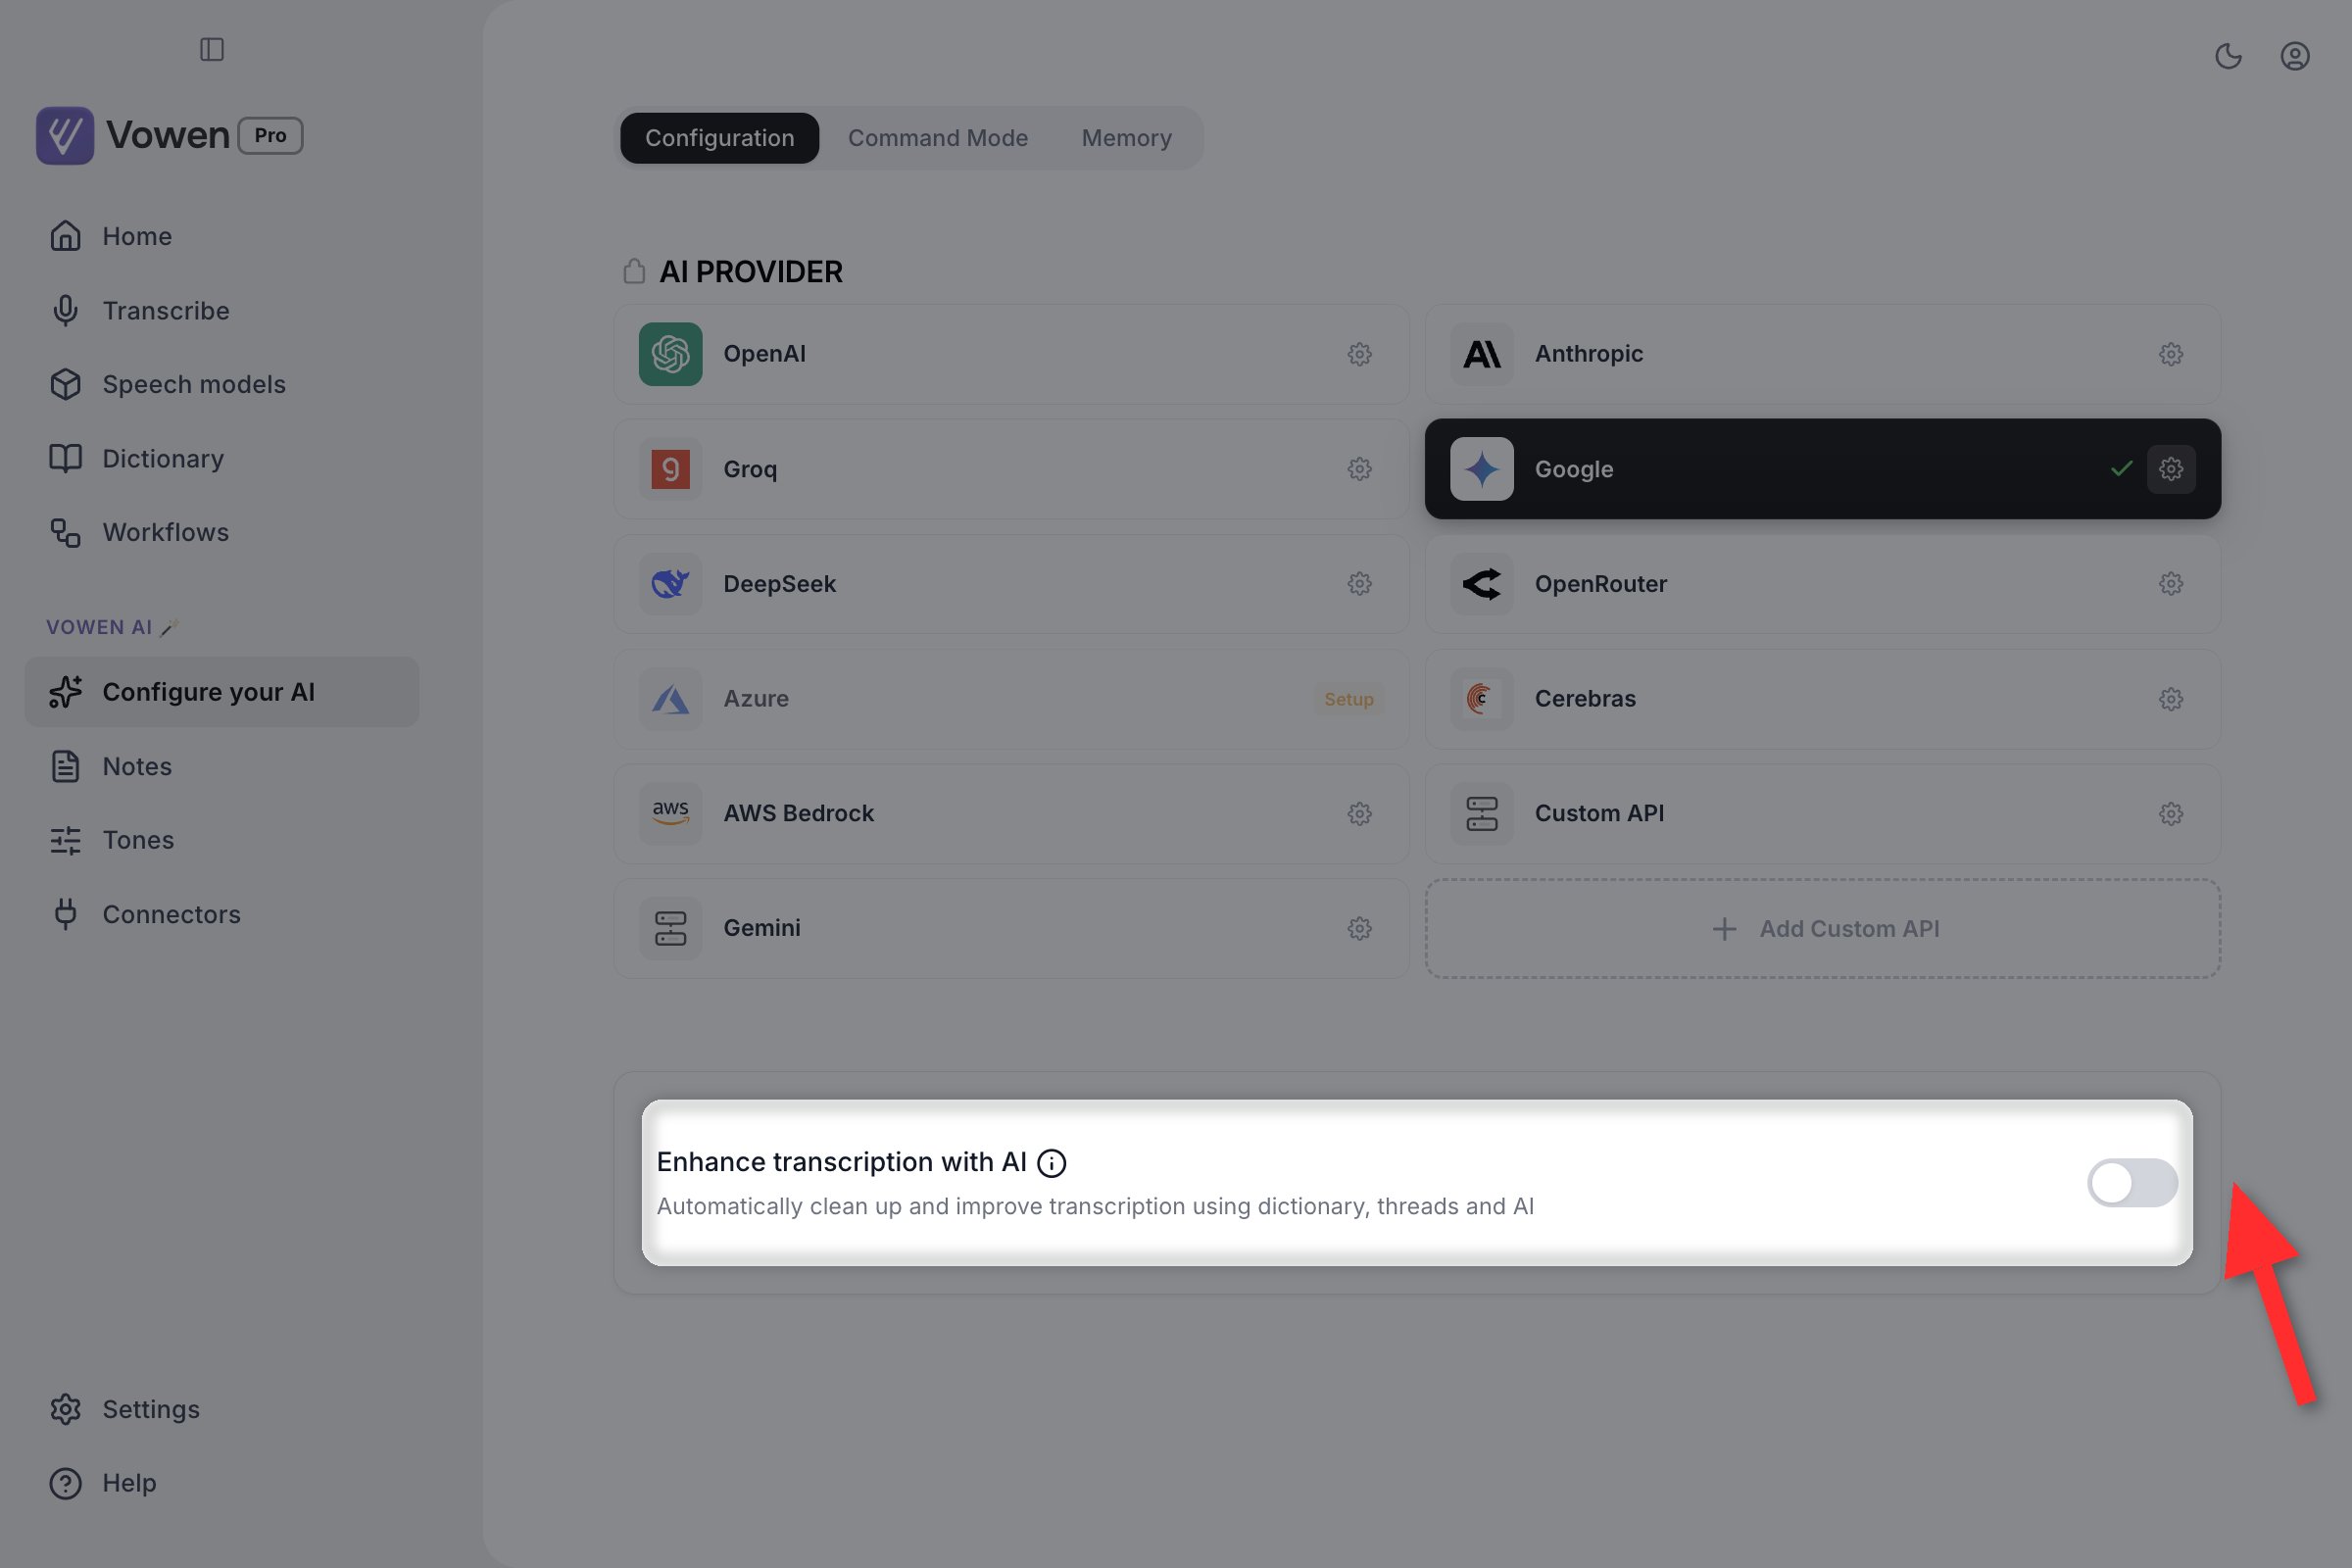
Screen context is **macOS only**, marked **Beta**, and **off by default**. The toggle only appears once AI enhancement is on and an AI provider is connected, because the feature works by adding names to the enhancement request.
Names are the hardest thing for a recognizer, and the correct spelling is often already on your screen in the Slack DM header, the member list, or the document title. This setting lets the AI enhancer use it.
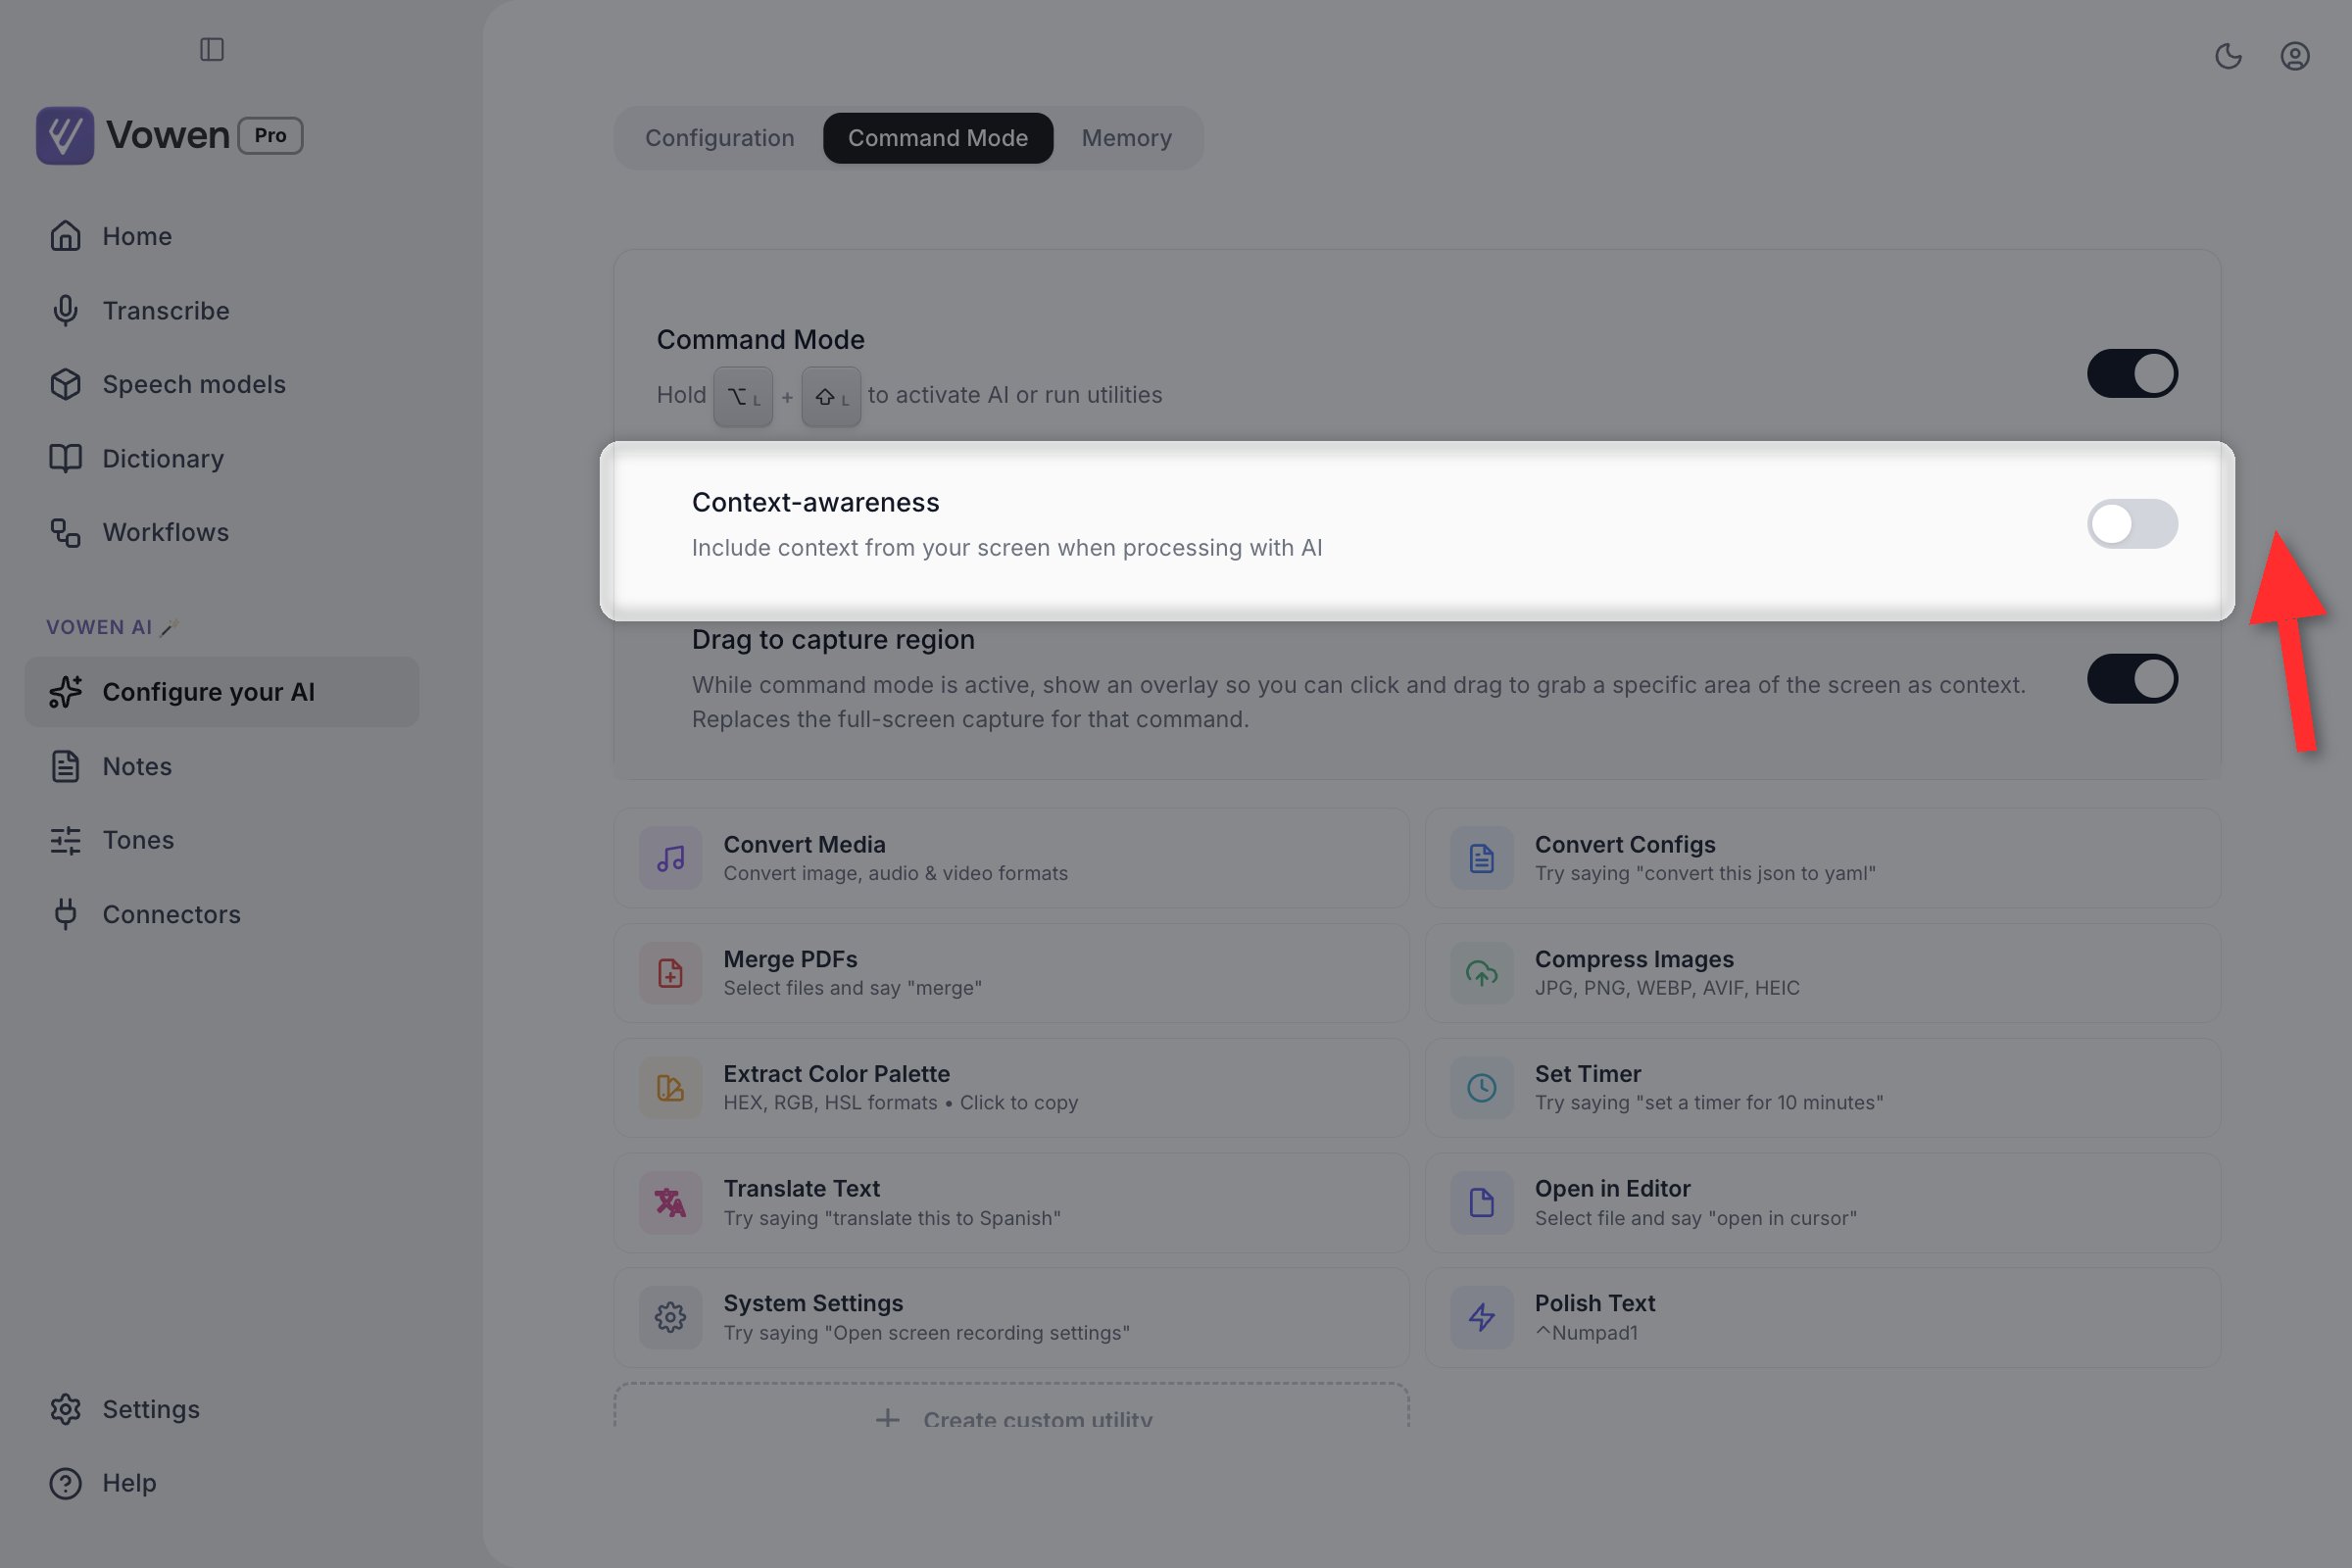 Find it under **Configure your AI** in the sidebar, nested beneath **Enhance transcription**: *Pass screen as context*.
How it behaves:
* It reads the **Accessibility tree** of the focused window. It is **not** screen recording and takes no screenshots.
* The capture starts when your dictation starts and never blocks it. If the reading is not ready when the transcript is, the dictation goes without it.
* It only runs when AI enhancement will run. No enhancement means no capture at all.
* The candidate names ride along with the enhancement request you are already making. There is no second model call.
* It is strictly **opt-in**. Until you turn it on, nothing from your screen is read or sent.
This sends text visible in your current window to your AI provider. Only turn it on if you are comfortable with that.
## Use Threads for long-form phrases
If you dictate the same long phrase repeatedly (a university name, a mailing address, a signature, a project tag), set it up as a Thread. Speak a short trigger and Vowen inserts the full text.
1. Open **Dictionary** in the sidebar and switch to the **Threads** tab.
2. Add a trigger (what you say) and a replacement (what gets inserted).
3. For example: say "my university" and Vowen inserts "Stanford University, Stanford, CA".
Full guide: [Threads (Snippets)](/features/threads).
## Enable AI Enhancement
For polished output, turn on [AI Enhancement](/ai-features/ai-enhancement). It:
* Fixes remaining spelling and grammar issues.
* Adds proper punctuation and capitalization.
* Formats numbers correctly, so "three thousand" becomes "3000".
* Applies spoken commands like "new paragraph".
 ## Filler word removal
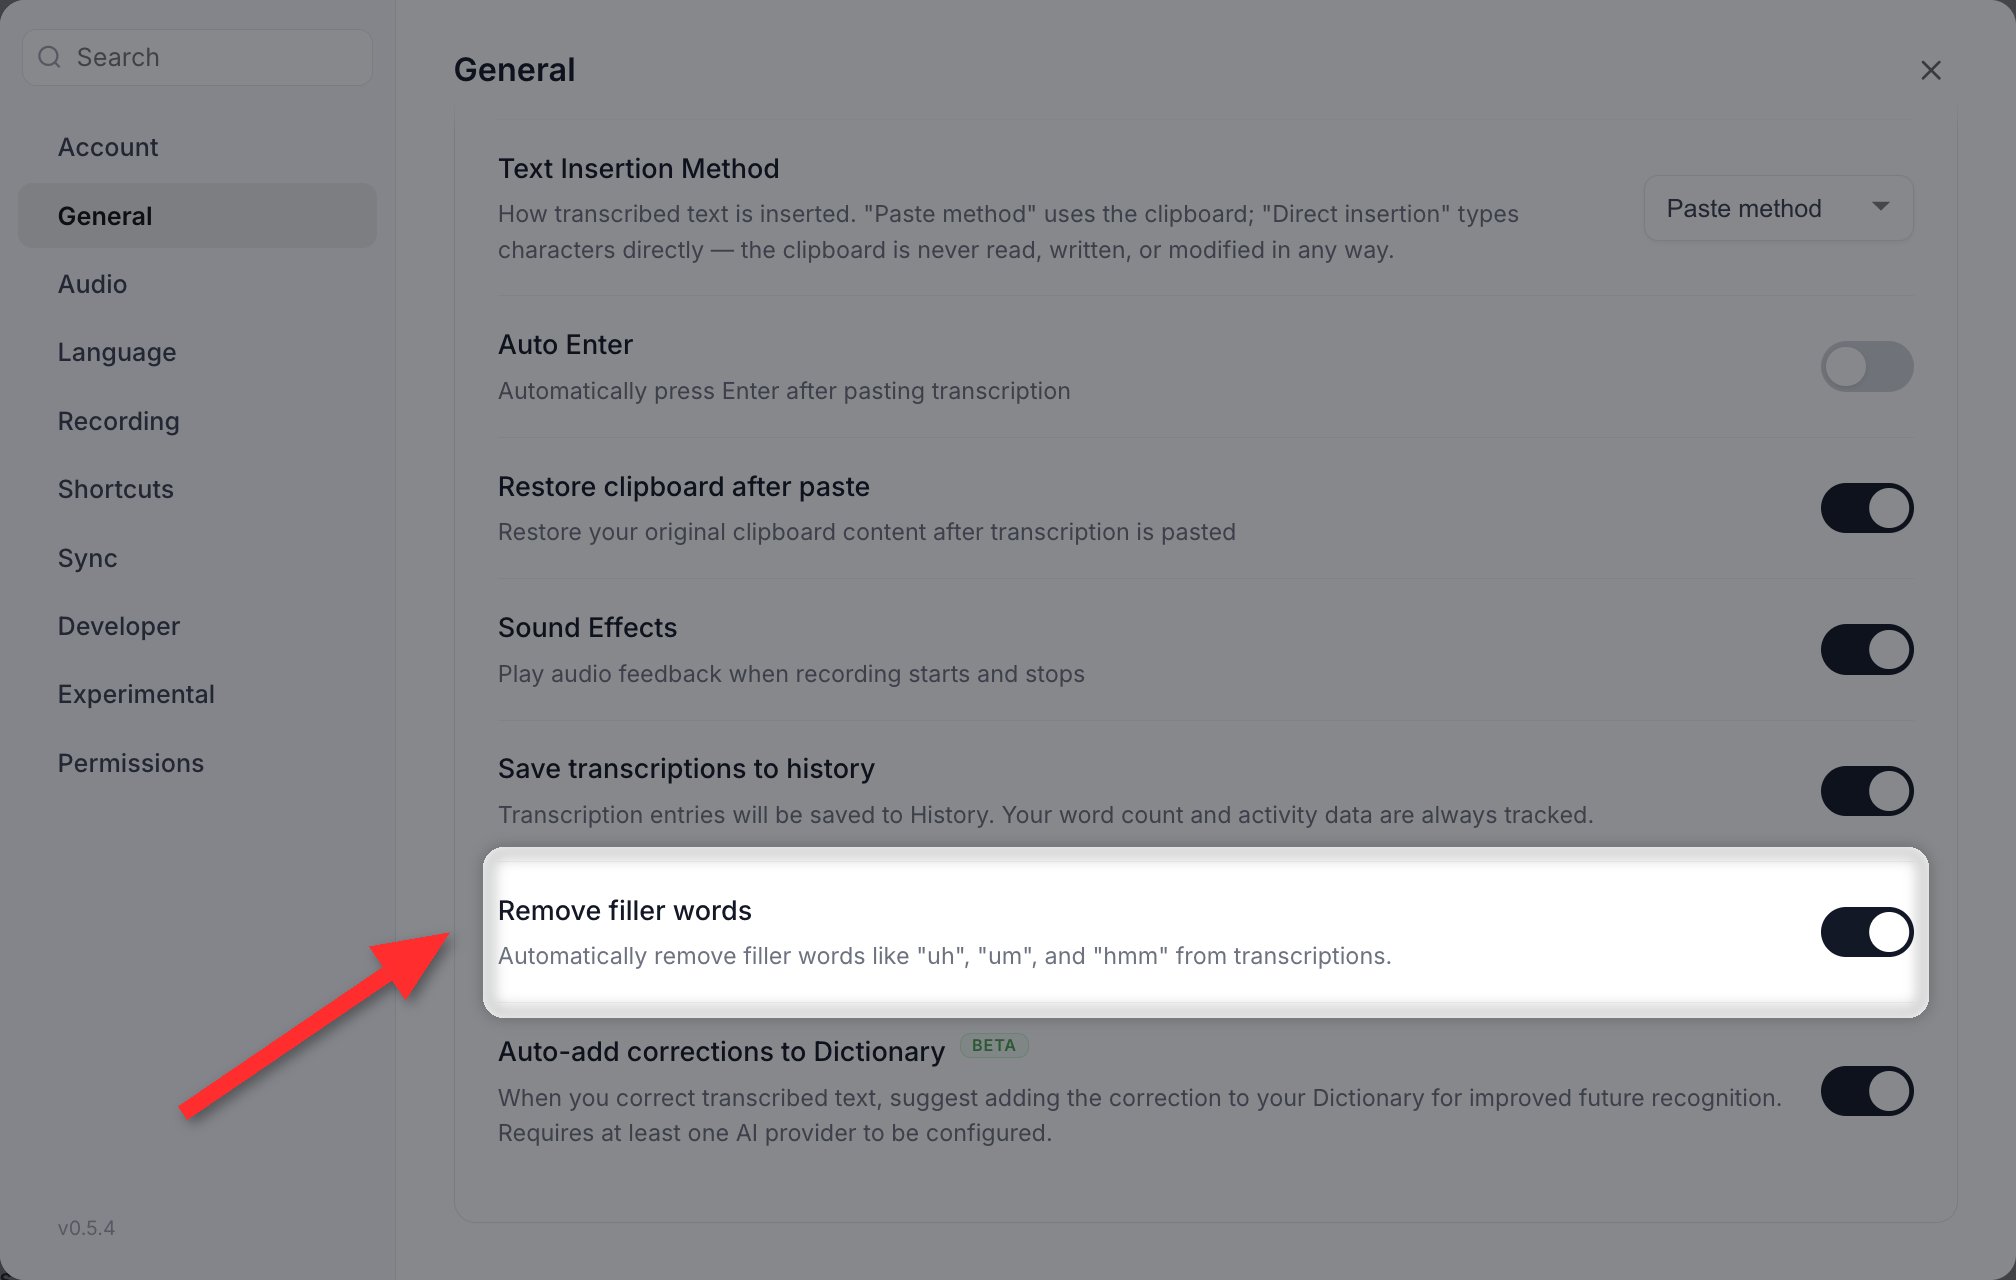
Vowen strips fillers like "um", "uh", "like" and "you know" before the text reaches AI Enhancement. This is on by default and works whether or not you have an AI provider connected. Toggle it in **Settings > General > Remove filler words**.
ElevenLabs Scribe v2 can also do this server-side: see the **Remove filler words and false starts** toggle in [Per-model options](/transcription/models#per-model-options).
 ## British spelling without an AI instruction
If your transcripts come back with American spellings, do not write an AI instruction for it. Set **Settings > Language > English spelling** to **British English**. It is a native, on-device converter that runs with or without AI enhancement. See [Languages](/transcription/languages#english-spelling).
## Backing up your Dictionary
Your Dictionary and Threads travel together in **Import / Export Data**, at the bottom of **Settings > Account**. Use it to move your terms between machines or keep a backup.
Import / Export Data is a Pro feature.
***
Running into accuracy issues? See the [Accuracy FAQ](/faq#accuracy).
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.